Best Local AI Models for Mac Mini
The Mac Mini is the cheapest way into local AI on Apple Silicon. The 2026 M6 with 16GB runs Qwen3.5 4B and 9B-class models comfortably, 24-32GB M6 configs step up to 14B-class models, and M5 Pro configs with 48-64GB handle 27B models, with active cooling that sustains speeds the fanless MacBook Air cannot.
On a Mac Mini, the best local LLM ranges from Qwen3.5 4B Instruct at 8GB to Qwen3.6 35B-A3B (Q8) at 64GB. That spans 8GB to 64GB configurations, where 90 of ModelFit's 106 local models fit comfortably at the top tier. Pick your exact chip below for its ranked list.
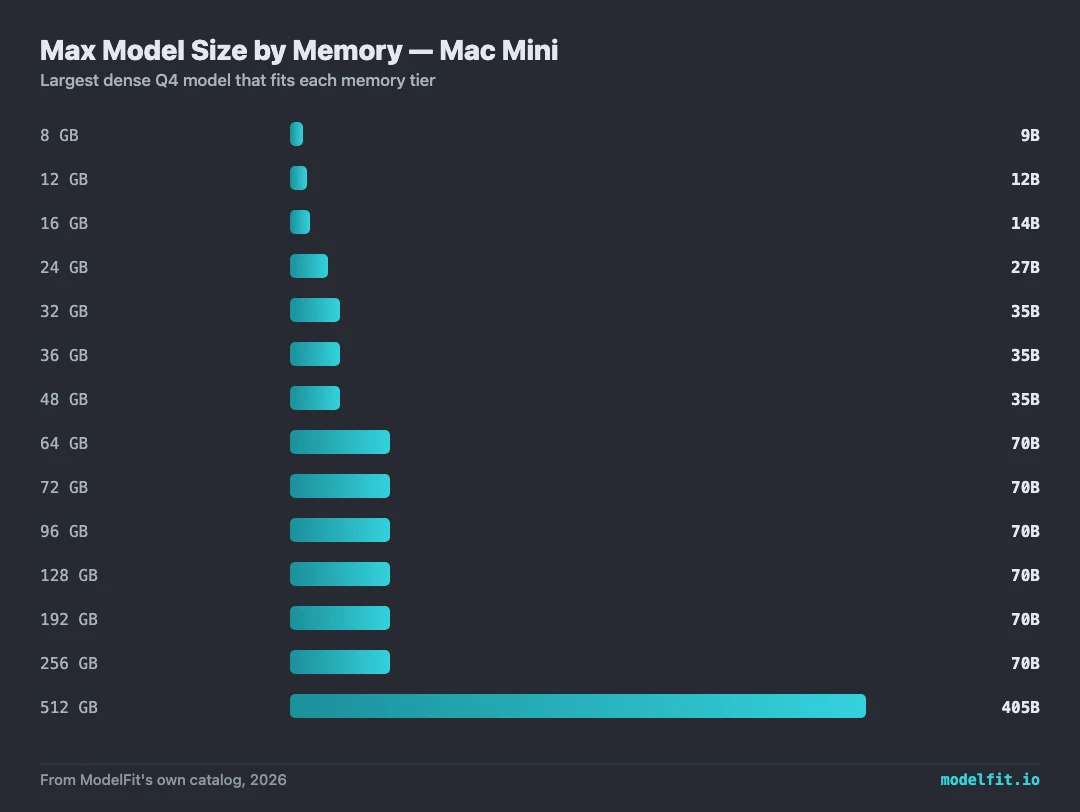
Sizing rule: a local model needs about 0.6 GB of unified memory per billion parameters at Q4, and ModelFit budgets roughly 70% of each configuration's RAM. At 8GB the best fit is Qwen3.5 4B Instruct (~3.5GB); at 64GB it is Qwen3.6 35B-A3B (Q8) (~38.7GB), reaching an estimated 21 tok/s. Mid-range configurations trade model size for speed between those two points. What it will not run: even the 64GB tier leaves Llama 3.3 70B Instruct (Q8) (70B) to a cloud API, and the 8GB tier caps out far earlier.
→ Pick your exact chip below for its ranked models and one-line install command.
Speeds are ModelFit estimates from chip bandwidth and model size, not measured benchmarks.
Cite this page: ModelFit, Best Local AI Models for Mac Mini, https://modelfit.io/mac-mini/, updated September 2026, CC BY 4.0.
Last updated: September 3, 2026 · Editor: ModelFit Team
Recommended Models
Best for quality, coding, reasoning. Strong fit for 16 GB RAM with balanced speed and quality.
Best for chat, coding. Strong fit for 16 GB RAM with balanced speed and quality.
Best for chat, coding, multimodal. Strong fit for 16 GB RAM with balanced speed and quality.
Best for agentic coding on small machines. Strong fit for 16 GB RAM with balanced speed and quality.
Best for vision, multimodal. Strong fit for 16 GB RAM with balanced speed and quality.
Best for chat, coding. Strong fit for 16 GB RAM with balanced speed and quality.
This model may feel memory-heavy on 16 GB RAM, but it is still listed for balanced speed and quality.
This model may feel memory-heavy on 16 GB RAM, but it is still listed for balanced speed and quality.
Context costs memory too. Qwen3.5 9B Instruct loads ~7 GB of weights; at 16k context the KV cache adds ~0.5 GB (still fits the ~11 GB usable RAM), and at 64k it adds ~2.0 GB (still fits).
KV-cache figures assume an fp16 cache, the llama.cpp/Ollama default. Standard GQA models use a size-class estimate (8 KV heads x 128 head dim class); hybrid linear-attention models (Qwen3.5/3.6, Qwen3-Next) use the exact per-token cost from their published config, since only their sparse full-attention layers cache KV. A q8_0 KV cache roughly halves either figure. Estimates, not measurements.
Pick Your Exact Mac Mini Chip
Where to Buy for Local AI
best configsCheapest way into the 24GB sweet spot: runs 14B models comfortably and 30B MoE via mmap.
Check price on AmazonMore headroomLoads 70B-class models and leaves room for a multi-model local stack.
Check price on AmazonPrefer to buy direct? Buy from Apple (same price, no affiliate link).
Archive your model library off the internal drive. Quantized models run 5 to 40GB each, so 2TB holds dozens with room to spare.
Check price on Amazon40Gbps external storage fast enough to run models from. Pair it with an M.2 drive for a portable model vault.
Check price on AmazonMore ports for the external drives, displays and peripherals around a local-AI workstation.
Check price on AmazonModelFit may earn a commission on purchases through these links, at no extra cost to you.
Need a Model Bigger Than This Mac Mini Runs?
by the hour70B-class and frontier open-weight models that won't fit in unified memory run great on an hourly rented GPU, same open weights, same Ollama workflow, no subscription.
ModelFit may earn a commission on sign-ups made through these links, at no extra cost to you.
The weekly local-AI refresh
New open-weight models, real Apple Silicon benchmarks, and the one model worth running on your Mac this week. Free, one email a week, unsubscribe anytime.
By subscribing you agree to our Privacy Policy and to receive the weekly email. Unsubscribe anytime.
Related Setup Guides
Mac Mini Local AI Articles
Qwen3.6 35B-A3B MoE runs at ~39 tok/s est. on the Mac Mini M5 Pro 48GB at Q4_K_M. Top picks for coding, reasoning, and agents with 307 GB/s bandwidth.
Best LLM for Mac Mini M5 Pro with 64GB RAM (2026)Qwen3.6 35B-A3B runs at Q8 with ~21 tok/s est. on the Mac Mini M5 Pro 64GB. Top picks for Q8 precision, dual-model setups, and 70B-fit headroom at 307 GB/s.
Best LLM for Mac Mini M6 with 16GB RAM (2026)Qwen3.5 9B leads the M6 Mac Mini 16GB tier at ~25 tok/s est. We ranked 5 Ollama models by speed and quality, with RAM usage and one-command install.
Best LLM for Mac Mini M6 with 24GB RAM (2026)GPT-OSS 20B and LFM2 24B-A2B lead the M6 Mac Mini 24GB tier. MoE models unlock 20B-class quality at ~27 tok/s est. on the $1,399 M6 config.
Best LLM for Mac Mini M6 with 32GB RAM (2026)Gemma 4 26B-A4B and Qwen3.8 27B lead the M6 Mac Mini 32GB tier at 170 GB/s. MoE models run at ~22 tok/s est., with ~22GB usable for LLMs.
Mac Mini for Local AI: Buy M4 Now or Wait for M5? (2026)Mac Mini entry price jumped from $599 to $799 while the M5 mini is rumored for October 2026. The honest buy now or wait math for local AI builders.
Popular Model Families
Frequently Asked Questions
What is the best AI model for Mac Mini?
The Mac Mini is the cheapest way into local AI on Apple Silicon. The 2026 M6 with 16GB runs Qwen3.5 4B and 9B-class models comfortably, 24-32GB M6 configs step up to 14B-class models, and M5 Pro configs with 48-64GB handle 27B models, with active cooling that sustains speeds the fanless MacBook Air cannot. On the default Apple M6 with 16GB RAM, Qwen3.5 9B Instruct is our top pick, handling models up to about 12B parameters at this RAM. Higher-RAM Mac Mini configurations, including Pro and Max tiers where available, reach into the 9B-27B parameter range.
What size models fit on Mac Mini?
With 16GB unified memory, Mac Mini runs models up to about 12B parameters comfortably. Strong picks include Qwen3.5 9B Instruct, Qwen3 8B, Gemma 4 12B. Higher-RAM configurations, including Pro and Max tiers where available, reach into the 9B-27B parameter range. Use the ModelFit wizard to match your exact RAM and chip.
How fast is local AI on Mac Mini?
Expect an estimated 25 tokens per second on the Apple M6 with optimized, quantized models. The Mac Mini M6 (2026) pairs 153 GB/s memory bandwidth (170 GB/s on 24GB and 32GB configs) with desktop cooling, so 9B-14B class models sustain full speed on long runs. In ModelFit estimates the 16GB config matches M5-class speed on a 7B Q4 reference (~32 tok/s); the M5 Pro option at 307 GB/s with up to 64GB lifts the ceiling to 27B-class models. Announced 2026-08-26, shipping September 22. (Speeds are ModelFit estimates, not measured benchmarks, and vary with model size and quantization.)