Apple announced the M5 Pro Mac Mini on August 26, 2026, with pre-orders opening same day and shipments starting September 22. The M5 Pro delivers 307 GB/s memory bandwidth, and the 48GB config starts at $1,699 with a 15-core CPU and 16-core GPU. This machine sits between the M6 Mac Mini and the Mac Studio: faster than the M6 for inference, more affordable than the Studio. It is built for developers and power users who want to run mid-size MoE and dense models locally without spending workstation money. Other configurations are covered on the Mac Mini device page.
TL;DR: The M5 Pro Mac Mini 48GB is the best value entry into serious local AI on Apple Silicon. Qwen3.6 35B-A3B at Q4_K_M loads in ~22GB and generates at ~39 tok/s est. thanks to its MoE design. For maximum quality at lower speed, Qwen3.6 27B at ~15 tok/s est. is the dense flagship. The 307 GB/s bandwidth makes MoE models fly: all six top picks fit comfortably with ~35GB of usable model memory. The Mac Mini M5 Pro 64GB tier adds Q8 quantization headroom, but 48GB already runs the models that matter.
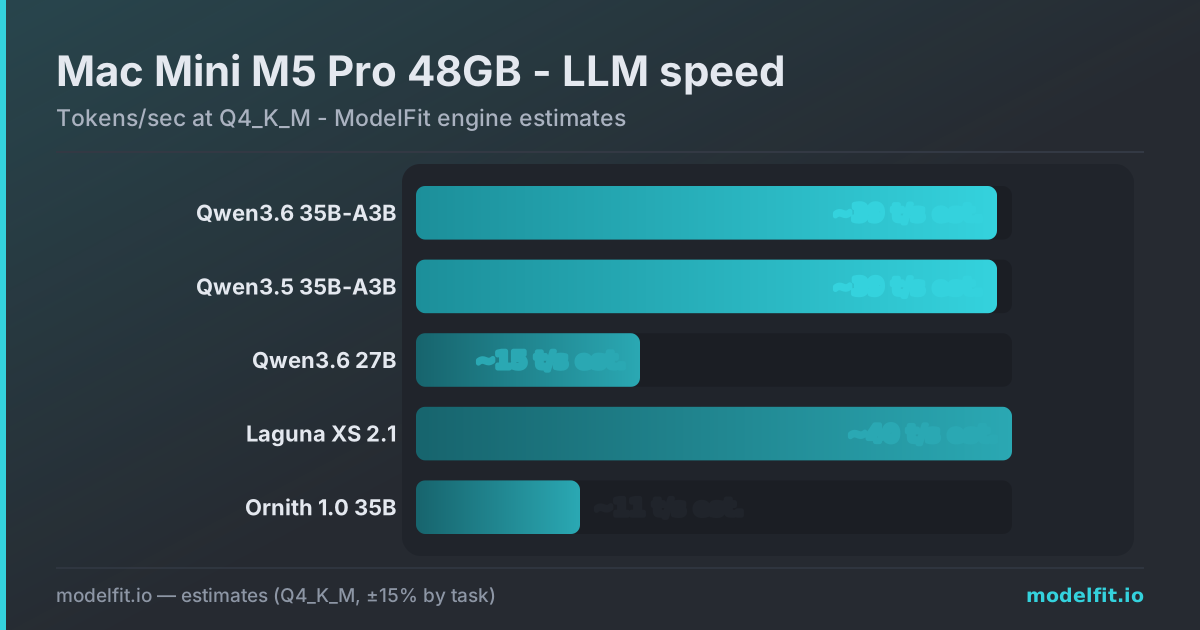 Estimated token generation on the Mac Mini M5 Pro 48GB at Q4_K_M. ModelFit engine estimates.
How 48GB Shapes Your Model Choices
On a 48GB M5 Pro Mac Mini, your real model budget is roughly 35GB. macOS and background services take about 4GB. Active apps like a browser, editor, and terminal claim another 3-4GB. That leaves just over half the machine for model weights and context.
| Allocation | Typical Size |
|---|---|
| macOS kernel + services | ~4 GB |
| Active apps (browser, editor, terminal) | ~3-4 GB |
| Available for LLM | ~35 GB |
Get told when a better model fits your Mac Mini M6 16 GB
One email when a new open-weight model beats these picks on your machine, plus the Thursday weekly.
For: Mac Mini M6 16 GB
The rule of thumb for Q4_K_M is roughly 0.6 GB per billion parameters. A 27B dense model needs about 18GB and fits with headroom. A 35B Q4 model lands near 21GB, also fine. But the Q4 math tells only half the story.
MoE (Mixture of Experts) models store all parameters in memory but activate only a subset per token. The memory cost tracks total parameters, while decode speed tracks active parameters. This split is what makes the 48GB tier interesting. A 35B MoE with 3B active parameters loads fully at ~22GB and decodes at ~39 tok/s est., near the speed of a much smaller dense model. By contrast, a dense 27B at Q4 loads ~18GB and decodes at ~15 tok/s est. because all 27B participate per token.
The practical takeaway: at 48GB, the top picks are MoE models. They give you 35B-class quality at small-model speed. For tasks that benefit from dense consistency (long-form writing, complex multi-turn reasoning), the dense 27B remains the quality playbook.
Best Models Ranked
| Rank | Model | Type | Size | Est. tok/s | Best for |
|---|---|---|---|---|---|
| 1 | Qwen3.6 35B-A3B | MoE 35B/3B active | Q4_K_M | ~39 tok/s est. | Reasoning, Coding, Agents |
| 2 | Qwen3.5 35B-A3B Instruct | MoE 35B/3B active | Q4_K_M | ~39 tok/s est. | Reasoning, Coding, Agent scenarios |
| 3 | Nemotron 3.5 Lightning 30B-A3B | MoE 30B/3B active | Q4_K_M | ~42 tok/s est. | Agentic, Coding, Long context |
| 4 | Qwen3.6 27B | Dense 27B | Q4_K_M | ~15 tok/s est. | Coding, Quality, Long context |
| 5 | GLM-4.7-Flash 30B-A3B | MoE 30B/3B active | Q4_K_M | ~42 tok/s est. | Coding, Agentic tasks, Reasoning |
| 6 | Laguna XS 2.1 | MoE 33B/3B active | Q4_K_M | ~40 tok/s est. | Agentic coding, Long-horizon tasks |
| 7 | Ornith 1.0 35B | Dense 35B | Q4_K_M | ~11 tok/s est. | Agentic coding |
| 8 | Qwen3 30B | MoE 30B/3B active | Q4_K_M | ~42 tok/s est. | Quality, Coding |
Model Details
Qwen3.6 35B-A3B is the top pick for the 48GB tier. It stores 35B parameters but activates only 3B per token, so it generates at ~39 tok/s est. while scoring near frontier levels on coding and reasoning. It loads at ~22GB and leaves 13GB of headroom for context and workflows.
ollama run qwen3.6:35b-a3bQwen3.5 35B-A3B Instruct is the same MoE architecture with an instruct tuning that prioritizes agentic scenarios and tool calling. If your work involves MCP workflows, structured outputs, or multi-step agent loops, this variant edges ahead.
ollama run qwen3.5:35b-a3bQwen3 30B activates 3B per token and ties the fastest estimate on this list at ~42 tok/s est. It trades some quality ceiling against the 3.5/3.6 generation for raw speed. A fast choice for chat-heavy and code-review workloads.
ollama run qwen3:30bNemotron 3.5 Lightning 30B-A3B is NVIDIA's hybrid Mamba-MoE: 30B stored, 3B active, and only 6 of its 52 layers use full attention, so the KV-cache stays a fraction of a dense 30B's and long contexts stay cheap. It loads at ~23.7GB and runs ~42 tok/s est.
ollama run nemotron-3.5-lightning:30bGLM-4.7-Flash 30B-A3B is Z.ai's local-class MoE (MIT, 3B active). It scores 59.2 on SWE-bench Verified per its model card, and at ~19GB it is the lightest 30B-class model here, at ~42 tok/s est.
ollama run glm-4.7-flashLaguna XS 2.1 is a 33B MoE activated at 3B, loading at ~20.3GB. Its agentic coding profile makes it strong for long-horizon tasks where the model needs to maintain context across many steps. Estimated at ~40 tok/s est.
ollama run laguna-xs-2.1:q4_K_MQwen3.6 27B is the dense flagship for this tier. At ~15 tok/s est. it is slower than the MoE models above, but it offers the consistency that dense architectures deliver. Best for long-form coding sessions, document analysis, and tasks where every token benefits from the full parameter set.
ollama run qwen3.6:27bWhat 48GB Cant Run
The 48GB tier cannot run Q8 quantizations of 27B+ models. Qwen3.6 27B at Q8 needs 30GB, and the 35B-A3B MoE at Q8 needs 38.7GB. Both fit on paper, but they eat most of your headroom leaving little for context or multitasking.
70B dense models do not fit at all. A Llama 3.3 70B at Q4 needs about 42GB, and that is before KV-cache for any meaningful context length.
If you need Q8 quality or 70B model access, step up to the Mac Mini M5 Pro 64GB or a Mac Studio with M5 Max or M5 Ultra. The 64GB M5 Pro Mini runs Q8 quants of all the models above, and the Studio unlocks 70B-plus models with higher bandwidth.
FAQ
What is the best LLM for Mac Mini M5 Pro 48GB?
Qwen3.6 35B-A3B at Q4_K_M is the top pick. Runs at ~39 tok/s est., loads in ~22GB, and scores highest on coding and reasoning among models that fit this tier. For dense quality at lower speed, Qwen3.6 27B at ~15 tok/s est. is the alternative.
Can the Mac Mini M5 Pro 48GB run a 70B model?
No. A 70B Q4 model needs roughly 42GB for weights alone, plus KV-cache for context. The 48GB Mac Mini does not have enough memory. If 70B is your target, step up to a Mac Mini M5 Pro 64GB or a Mac Studio.
Is the Mac Mini M5 Pro worth it over the M6 for local AI?
Yes, for mid-size models. The M5 Pro has 307 GB/s bandwidth versus the M6 at 153-170 GB/s. That double bandwidth means MoE models like the 35B-A3B class run at roughly double the token speed. The M6 Mac Mini is a great entry point (read our M6 Mac Mini guide), but the M5 Pro is the step up where MoE models become genuinely fast.
48GB or 64GB?
48GB is the value sweet spot. It runs every 35B-class MoE model at Q4 with headroom. 64GB adds Q8 quantization for the same models, which improves quality modestly at the cost of half the token speed. If you care about running models at the highest precision your hardware allows, get 64GB. If you want maximum speed per dollar, 48GB is the answer.
Why do MoE models dominate the 48GB tier?
MoE activates a fraction of total parameters per token, so decode speed tracks active params (3B) rather than total params (35B). The memory cost is still for 35B, but at Q4_K_M that means ~22GB, well within 48GB. You get 35B-class quality at small-model speed. Dense models of similar size decode slower because every token touches all parameters.
Don't miss the next one for your Mac Mini M6 16 GB
This article covers one moment. Get one email when a newer open-weight model fits your machine better, plus the Thursday weekly with what changed.
For: Mac Mini M6 16 GB
Where to Buy for Local AI
best configsArchive your model library off the internal drive. Quantized models run 5 to 40GB each, so 2TB holds dozens with room to spare.
Check price on Amazon40Gbps external storage fast enough to run models from. Pair it with an M.2 drive for a portable model vault.
Check price on AmazonMore ports for the external drives, displays and peripherals around a local-AI workstation.
Check price on AmazonCheapest way into the 24GB sweet spot: runs 14B models comfortably and 30B MoE via mmap.
Check price at AppleMore headroomLoads 70B-class models and leaves room for a multi-model local stack.
Check price at AppleModelFit may earn a commission on purchases through these links, at no extra cost to you.
Have questions? Reach out on X/Twitter