DeepSeek Models: Cloud V4, Local R1 Reasoning
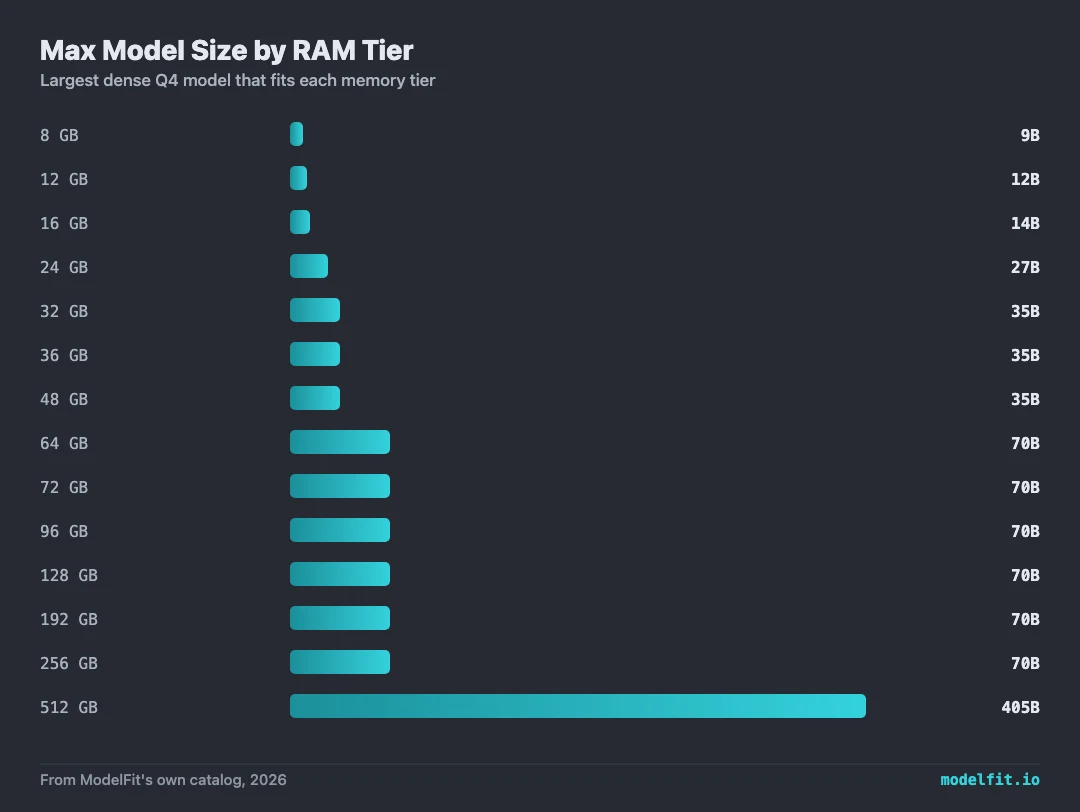
DeepSeek's V4 generation is a cloud story. V4.1 Flash (released 2026-09-10, MIT) is a multimodal image + text MoE with a 552B backbone and a 196B Engram conditional memory that activates 8B on prefill and 16B on decode, with 1M context. V4 Flash 0731 (284B total / 13B active) and V4 Pro (1.6T total / 49B active) are API models, and none of the three has a registry-verified Ollama tag. The local DeepSeek line is R1: the 7B, 14B and Llama 70B distills run in Q4_K_M via Ollama starting at 8GB RAM, and the full R1 671B needs a 512GB Mac Studio. V4 Flash 0731 does get community 2-bit dynamic quants that fit 128GB Macs through MLX, llama.cpp or the ds4 engine.
All DeepSeek Models
| Model | Size | Quant | VRAM | Min RAM | Best For | Quality | Ollama |
|---|---|---|---|---|---|---|---|
| DeepSeek-R1 Distill Qwen 7B | 7B | Q4_K_M | 5.5 GB | 8 GB | Reasoning, Coding | 80 | |
| DeepSeek-R1 Distill Qwen 7B (Q8) | 7B | Q8_0 | 7.5 GB | 16 GB | Reasoning, Coding | 82 | |
| DeepSeek-R1 Distill Qwen 14B | 14B | Q4_K_M | 11 GB | 16 GB | Reasoning, Quality | 86 | |
| DeepSeek-R1 Distill Qwen 14B (Q8) | 14B | Q8_0 | 14.6 GB | 24 GB | Reasoning, Quality | 88 | |
| DeepSeek-R1 Distill Llama 70B | 70B | Q4_K_M | 42 GB | 64 GB | Reasoning, Quality | 85 | |
| DeepSeek-R1 671B | 671B | Q4_K_M | 380 GB | 512 GB | Reasoning, Coding | 96 |
Cloud / API-only models
Weights are open but far beyond consumer hardware — these run as APIs. Each page lists the local alternatives.
| Model | Size | Access | Best For |
|---|---|---|---|
| DeepSeek V4 Flash 0731 | 284B | API only | Reasoning, Coding, Long context |
| DeepSeek V4.1 Flash | 552B | API only | Agentic coding, Reasoning, Long context, Vision |
| DeepSeek-V3 | 671B | API only | Quality, Coding |
| DeepSeek-V3-0324 | 671B | API only | Quality, Coding |
| DeepSeek-R1 | 671B | API only | Reasoning, Quality |
| DeepSeek V4 Pro | 1600B | API only | Frontier reasoning, Coding |
Device Compatibility
Which DeepSeek models can run on each device class, based on minimum RAM requirements.
| Model | iPhone | Air | Pro | Studio | Mini |
|---|---|---|---|---|---|
| DeepSeek-R1 Distill Qwen 7B (7B) | Possible | Possible | Excellent | Excellent | Excellent |
| DeepSeek-R1 Distill Qwen 7B (Q8) (7B) | No | Possible | Possible | Excellent | Possible |
| DeepSeek-R1 Distill Qwen 14B (14B) | No | Possible | Possible | Excellent | Possible |
| DeepSeek-R1 Distill Qwen 14B (Q8) (14B) | No | Possible | Possible | Possible | Possible |
| DeepSeek-R1 Distill Llama 70B (70B) | No | No | Possible | Possible | Possible |
| DeepSeek-R1 671B (671B) | No | No | No | Possible | No |