Local LLM Guides & Field Notes
Field notes: guides, comparisons, and insights on running local LLMs on Apple Silicon.
This blog covers running local LLMs on Apple Silicon (MacBook Air, MacBook Pro, Mac Studio, Mac mini) and iPhone, plus NVIDIA and AMD GPU hardware picks for local AI. Expect device by RAM tier comparisons, Ollama setup guides, and coverage of new model releases as they land.
Every post links back to the underlying data: hardware fit tables, GPU tok/s estimates, and the model catalog behind ModelFit's recommendation engine. Start with a hub below, or browse the latest articles.
Can a 16GB Mac Run NVIDIA Nemotron 3.5 Bolt E4B? Yes, at 7.9GB
Yes. NVIDIA Nemotron 3.5 Bolt E4B runs on Apple Silicon today, and a 16GB Mac holds it with room to spare. Ollama's nemotron-3.5-bolt:e4b tag downloads 7,908,812,809 bytes, about 7.9 GB, made of the 6...
The weekly local-AI refresh
New open-weight models, real Apple Silicon benchmarks, and the one model worth running on your Mac this week. Free, one email a week, unsubscribe anytime.
By subscribing you agree to our Privacy Policy and to receive the weekly email. Unsubscribe anytime.
All articles
Can a 48GB Mac Run Recursive Flint int4? 22.580 GB
Yes, and 48 GB is precisely where Recursive draws the line for its own engine. The int4 MLX repository of Flint weighs 22.580 GB, 22,580,274,020 bytes across its five weight shards plus tokenizer and ...
Strata Runs Qwen3.8-Flash-Next 125B on a 32GB Mac (2026)
Strata, a free MIT-licensed engine built around one model, runs Qwen3.8-Flash-Next (125B parameters, 6B active) on Apple Silicon Macs by keeping the busiest experts in memory and streaming the rest fr...
Can a 32GB Mac Run Perplexity Computer Local? 19.4 GB at 4-bit
A 32GB Mac mini M6 cannot run Perplexity Computer in fully local mode. Perplexity recommends 36 GB of unified memory or more for that mode, and Apple caps the standard M6 Mac mini at 32 GB. The same m...
NVIDIA Dory 1.0 4B on a Mac: 3.7GB Fits 16GB, Fork Build Needed
NVIDIA published NVIDIA-Nemotron-Labs-Dory1.0-4B on October 16, 2026, and the memory question is settled before it starts: the smallest official build is a 3.673 GB quantized GGUF. That file fits insi...
Best Mac Mini M6 Config for Local AI: Buy RAM, Not Apple's SSD (2026)
The best Mac Mini M6 for local AI is the 32GB model with the base 256GB SSD at $1,299, and the 24GB build at $1,099 is the budget floor. Both are build-to-order configs, paired with an external 40Gbps...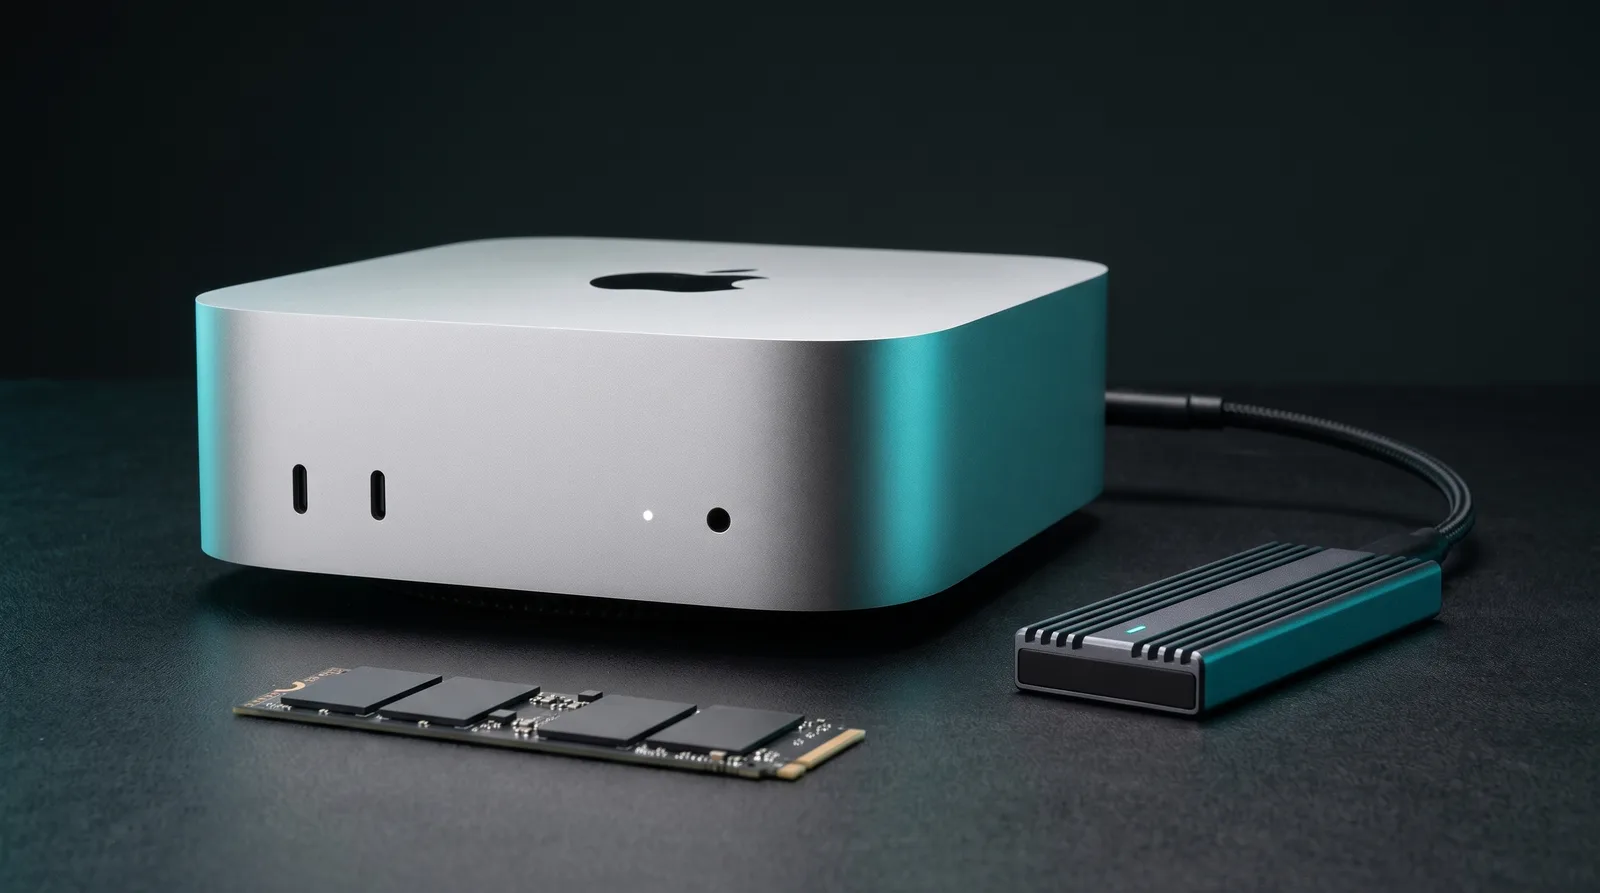
Meta Muse Spark Open on a Mac: 304GB 2-bit Build Needs a 512GB Mac Studio
Meta released the weights of Muse Spark Open on October 15, 2026, an 816B-parameter Mixture-of-Experts model with 42B active parameters and a 1M-token context window, and shipped it with an Apple stor...
NVIDIA Nemotron 3.5 Bolt on a Mac: 22GB Needs a 36GB Mac, No Metal Yet
NVIDIA Nemotron 3.5 Bolt 74B-A9B, released on Hugging Face on October 15, 2026, is a 74B vision-language model that NVIDIA compressed and quantized "to fit in 24GB of memory" (NVIDIA model card, 2026)...
NVIDIA RTX Spark Ships Oct 16: 128GB Unified Runs a 125B Locally
NVIDIA RTX Spark laptops go on sale Friday, October 16, and the number Mac owners will recognise is the memory ceiling: up to 128GB of unified LPDDR5X, the same ceiling as the top M5 Max configuration...
JetBrains Mellum2.1 on a Mac: 8.1 GB at Q4, 16 GB Is the Real Floor
JetBrains shipped Mellum2.1 on October 8, 2026, the next version of its 12B mixture-of-experts coding model, and this time it brought an official GGUF. That matters because the model is built to do ag...
Qwen-Image 2.1 Turbo on a Mac: 4.20 GB at Q4, 32.5 GB at BF16
Qwen-Image 2.1 Turbo is the 8-step distilled checkpoint of Qwen-Image 2.1, published on 2026-10-09, and it is the first build in that family a Mac can realistically generate images with. Community por...
Liquid's open d1 Runs on Any Mac: a 3B Model That Returns Decisions in 30 ms With Zero Output Tokens
Liquid AI published the open d1 decision models on 2026-10-07, and unlike most multi-billion-parameter releases this one fits the laptop you already own. d1-3B packs 3.12 billion parameters, answers t...
AREX-2 on a Mac: 17.20 GB at Q4 and a 16 GiB KV Cache
BAAI published AREX-2, a 27B multimodal agent model, on 29 September 2026 under Apache-2.0. The community had GGUF quants out the next day. That turns the usual "will it ship" question into a sizing q...
Ollama v0.40.0 Runs Models on MLX by Default on Apple Silicon: What Changes on Your Mac
Ollama v0.40.0 changes which runtime your Mac uses, not which models exist. On Apple Silicon, model architectures that the MLX runtime supports now run on MLX automatically, so a model that used to la...
Kolibri 1 on Mac: 36GB Runs the 2-Bit Build, 64GB the 4-Bit, and llama.cpp Now Supports It
Aleph Alpha released Kolibri 1 on 3 October 2026 under Apache-2.0: a German and English mixture-of-experts model with 78 billion total parameters that use 3.46 billion per token. There is no Mac path ...
Cloudflare Clef on Mac: Flash Fits 16 GB, 27B Needs 32 GB
Cloudflare uploaded Clef and Clef Flash to Hugging Face on 30 September 2026. For Mac users, therefore, the answer splits cleanly by memory tier. Clef Flash, the 9B model, runs on a 16 GB Apple Silico...
Kev Gives Your Mac a Jev-Style Decision Model: Kev-0.8B Fits Any Apple Silicon, Kev-27B Wants 96 GB
Kev is a four-model family of Jev-style decision models published by Jared Palmer under Apache-2.0, and the Mac question has a short answer and a long one. The short answer: Kev-0.8B is documented for...
CLM-8B Runs a Decision in One Forward Pass: 5.1 GiB on a Mac, If You Can Load It
CLM-8B is a decision model, not a chat model. A decision model is a network that reads one state plus a set of typed questions and returns labels or probability distributions, with no tokens generated...
Nimble and Tev1 on Mac: What Ollama's Decision Lane Costs
Ollama published v0.35.0 on 28 September 2026, and for the first time the runtime serves models that answer instead of writing. Decision models are models that return a choice, a score and a probabili...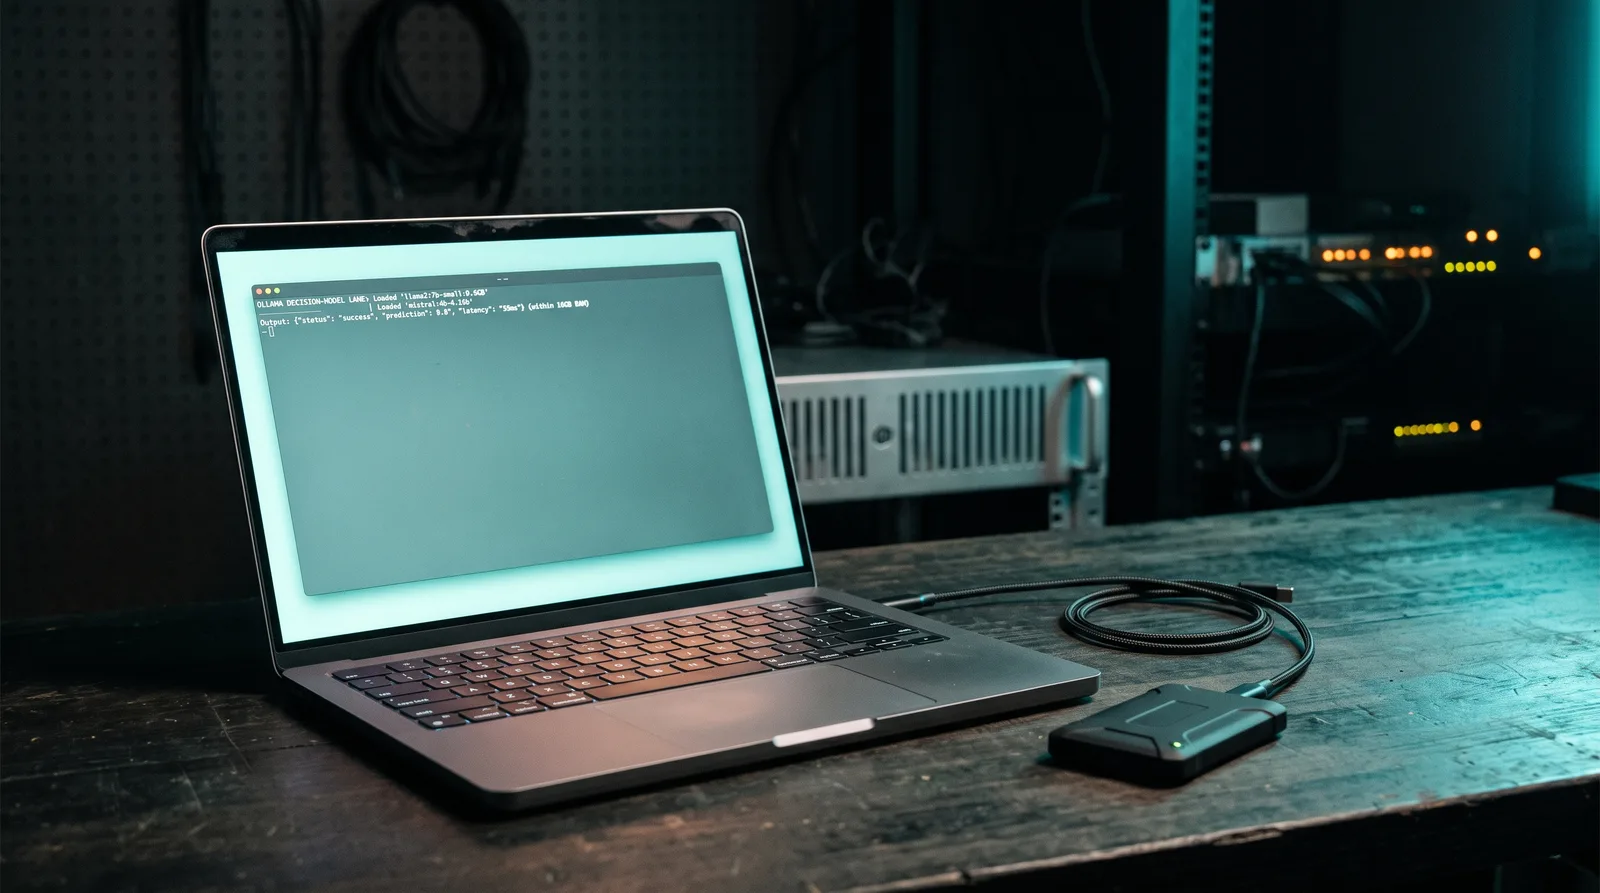
Laya Runs a 421M Decision Model on Your Mac in 13ms: System One Models Without a GPU
Laya is not a chatbot and it never writes a token. It reads a state (an email, a ticket, a JSON blob) plus typed questions, and it returns calibrated probabilities in one forward pass. Convai Innovati...
llama.cpp 42x Drafting on an M4 Pro: What It Does Not Buy
Hayder Tirmazi published a set of optimisations to prompt lookup drafting in llama.cpp on 26 September 2026. He measured them on an Apple M4 Pro with 14 cores and 48 GB of memory, and he reports up to...
macOS 27 Ships a Free On-Device LLM in Your Terminal: What the fm CLI Does Well and Where the 4,096-Token Limit Bites
Every Mac running macOS 27 has a language model behind a shell command. It sits at /usr/bin/fm, it answers without an account, an API key or a model download from a hub, and it ships with the operatin...
Linux With GPU Acceleration Now Boots on the M4 Mac Mini: Can You Run Local LLMs on It Yet?
On September 18, 2026, Gravity Linux published an early alpha that boots a Fedora remix with KDE Plasma on Wayland on the 2024 base M4 Mac mini, with a working display controller and GPU driver. That ...
Ling-3.0-flash-VL Puts 124B Parameters in a Model That Computes Only 5.5B: What a Mac Needs
Ling-3.0-flash-VL is InclusionAI's open-weight vision-language model, and it is the cleanest sparse mixture-of-experts test case of 2026 for Apple Silicon. A mixture-of-experts (MoE) model is one that...
Qwen3.8-27B Finetunes That Think 37% to 58% Less: Which One Actually Fits Your Mac
A 24GB Mac can run both new token-efficient Qwen3.8-27B finetunes through GGUF, but only at lighter quantization tiers. BottleCap AI's ThinkingCap and UkisAI's Swift 1.5 each publish a range of GGUF f...
Splash Engine Requirements: Which Macs Run Inco's 36GB AI Engine (2026)
Splash is an open-source inference engine from Inco AI that runs only on Apple Silicon, and it asks for more memory than most local LLM tools. The stated floor is an M3 chip or newer, macOS 26.4 or la...
Swiftlet: 80B MoE in 4.3 GB of RAM on a Mac
An 80-billion-parameter model running on a MacBook with 24 GB of unified memory, at a peak of 4.3 GB of RAM, is not supposed to be possible. The rule everyone repeats is that a model must fit in memor...
Run Concurrent LLM Requests on Your Mac: vllm-metal 0.30.0
Every local LLM setup on a Mac has been a single-user machine. One prompt, one agent, one stream of tokens. vllm-metal is the community plugin that puts vLLM's scheduler, paged KV cache and OpenAI-com...
Ollama 0.34.4 on Mac: Qwen 3.8 Prefill +19%, Gemma 4 Fix
Ollama is the runtime that puts llama.cpp and MLX behind one command line, and v0.34.4 shipped as a stable release on September 23, 2026. It landed one day after its release candidate. Most of the cha...
Qwen-Image 2.1 on Mac: No Official Apple Silicon Path
Qwen-Image 2.1 is the image model that Alibaba's Qwen team released on September 20, 2026. It is a 7B single-stream DiT that generates and edits images with one set of weights, and it ships with nativ...
Ternary-Bonsai 2 27B: 6 GB on a Mac, No Stock Runtime
Ternary-Bonsai 2 27B is Prism ML's full 27B-class model shipped as a single 5,946,648,928 byte file: 5.95 GB, or 5.54 GiB, of ternary language weights. That is a 27B inside a 16 GB Mac's budget. The w...
Xiaomi MiMo-V2.6 on a Mac: 9B Fits 16GB, Flash Needs 256GB
Xiaomi MiMo published the MiMo-V2.6 family on 21 September 2026 under the MIT license, and exactly one of its three checkpoints is an everyday Mac model. MiMo-V2.6-Distill-Qwen-9B is a supervised fine...
Jev's System One Idea Was Open-Sourced a Year Earlier
TypeSafe AI launched Jev on September 16, 2026, calling it the first "System One" model. Jev does not generate text token by token. It returns probability distributions, confidence intervals and schem...
Bonsai 2 27B on a Mac: 5.9 GB, and the Fork It Needs to Run
Prism ML released Bonsai 2 27B on September 16, 2026, a ternary rebuild of Qwen3.8-27B whose entire language model is one 5,946,648,928 byte file. On paper that is the easiest Mac story of the year: 5...
M5 Macs and the Metal Tensor API: Why llama.cpp Fails to Start and the Fix to Use
If you run a local LLM on an M5 Mac, the first question is whether the model loads at all. On M5, M5 Pro and M5 Max machines, reports on macOS 26.2 through 26.4 describe ggml compiling its Metal libra...
GLM-5.3 VRAM Requirements: What Actually Loads on a Mac in 2026
GLM-5.3 is the largest open-weights model Z.ai has shipped: a 753B-parameter mixture-of-experts that activates 40B parameters per token. Its smallest official GGUF is 217 GB, so no MacBook can hold it...
DeepSeek V4.1 Flash on a Mac: Which Quantizations Actually Fit Your Memory
DeepSeek-V4.1-Flash activates 8 billion parameters per token during prefill and 16 billion during decode, which sounds like laptop territory. It is not. Unified memory is the single pool that Apple Si...
Mistral Small VRAM Requirements (2026)
Mistral Small 22B is the quiet value pick of the mid-size class. At 17 GB loaded, it sits exactly at the boundary between 16GB and 24GB hardware, which is why it is so often mis-sized. It does not fit...
Why We Never Recommend 2-Bit Quants (2026)
A popular hardware checker, willitrunai.com, grades a 1-bit quantization of GPT-OSS 20B as an A-tier fit for a 16GB card, right next to its own label of "Very Low" quality. That single page explains w...
DeepSeek V4 VRAM Requirements (2026)
The honest answer is that DeepSeek V4 has no VRAM requirements, because you cannot run it locally. DeepSeek has not released V4 or V4 Pro weights, and the parameter count is undisclosed. It is a cloud...
Llama 4 GPU Requirements: Scout and Maverick (2026)
Llama 4 has the largest memory requirements of any widely used open family, and the gap between the two variants is the story. Scout (109B total, 17B active) needs 67 GB at Q4. Maverick (400B total, 1...
llama.cpp 0.4.0 on Mac: Lazy Tensors, Sparse Attention, Thunderbolt RDMA (2026)
llama.cpp 0.4.0 landed on September 4, 2026, and three of its changes directly affect what fits on your Mac. First, lazy tensor reading lets oversized embedding tables stream from SSD instead of sitti...
How Much VRAM Do You Need for Local LLMs? (2026)
VRAM is the one spec that decides what you can run locally, and it is the one most guides get wrong by counting "loads" as "runs." The rule is simple: a model needs its quantized weights plus context ...
Best LLM for a 16GB Mac (2026)
A 16GB Mac is the most common local AI machine, and the most misconfigured. macOS reserves a share of memory before any model loads, so the usable pool is about 11 GB, not 16. That maps cleanly to 8B-...
Run a 125B MoE on a 48GB Mac: SlotStream Streams Experts from SSD at ~12 tok/s
SlotStream is a native Swift/MLX engine that runs Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model that weighs 103.8 GB at 4-bit, on ordinary Apple Silicon Macs by keeping only a bounded ...
Best AI Models for 8GB VRAM (2026)
8GB is the entry tier for local AI on a discrete GPU, and in 2026 it is a genuinely useful one rather than a consolation prize. An RTX 4060, 3070, or 4060-class laptop GPU runs 3B to 8B models at inte...
Best AI Models for 24GB VRAM (2026)
24GB is the most contested GPU memory tier, and it earns that reputation from both directions at once. An RTX 3090, RTX 4090, or RX 7900 XTX can run genuine 27B-32B dense models fully in VRAM, and 20B...
Gemma 4 GPU Requirements: Every Variant (2026)
Gemma 4 is a family, not a model, and its VRAM requirements span a factor of ten. The E2B edge variant loads in 2.3 GB while the 31B dense flagship wants 20 GB. Picking the wrong variant for your hard...
GPT-OSS 20B VRAM Requirements (2026)
GPT-OSS 20B is OpenAI's open-weight release from August 2025: a 21B-parameter mixture-of-experts model with only 3.6B parameters active per token, and its memory story is unusual enough that it gets m...
NVIDIA PAIR: Your Mac Just Became a Node in a Local AI Cluster (2026)
NVIDIA released PAIR (Personal AI Router) as a public beta on September 3, 2026, and it is the first tool that turns several home computers into one distributed inference cluster without special hardw...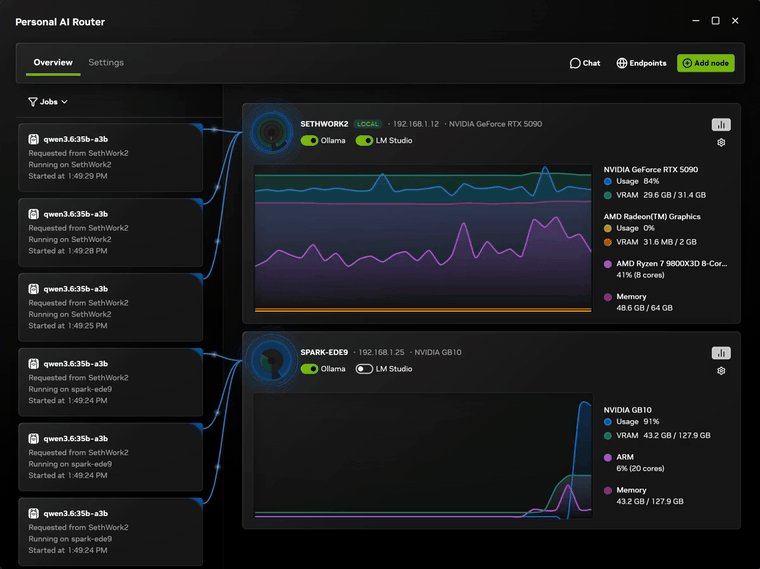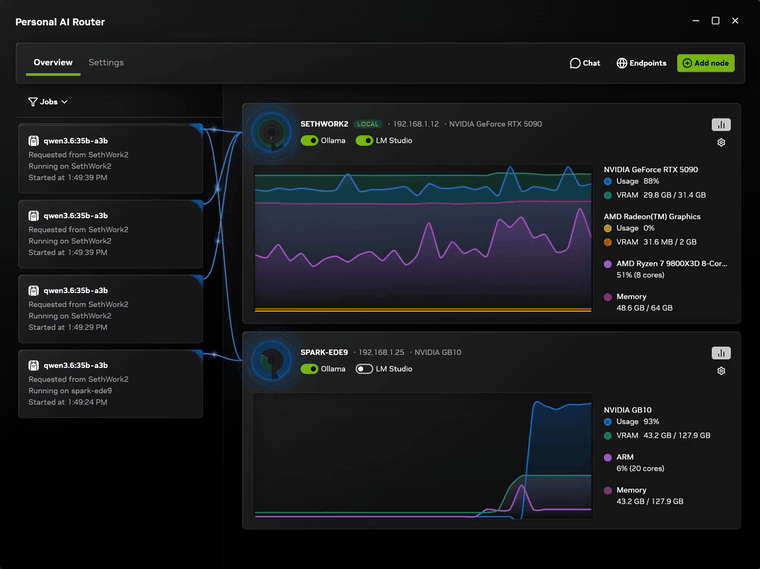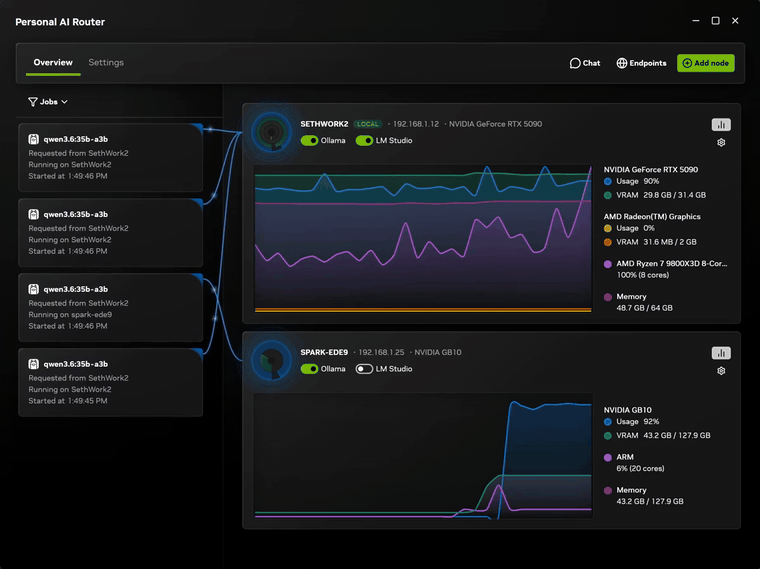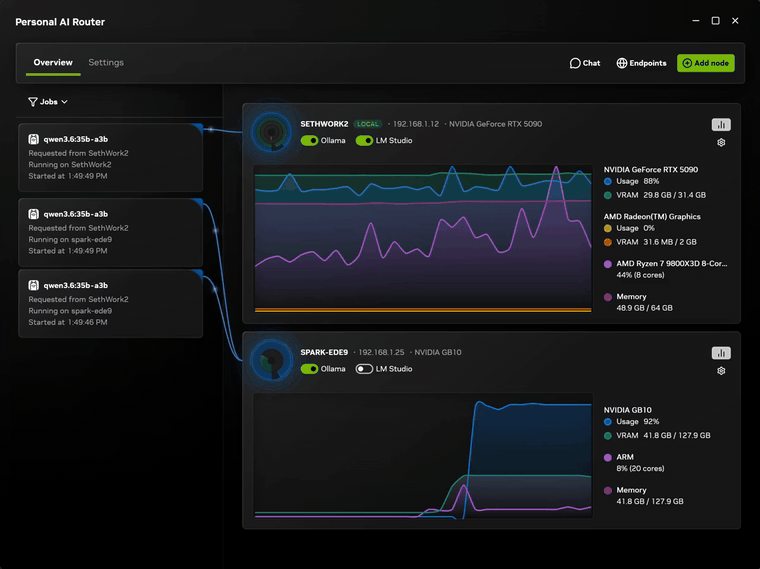
Qwen 3.5 122B-A10B VRAM Requirements (2026)
Qwen 3.5 122B-A10B is the largest model in the Qwen 3.5 family: a 122B-parameter mixture-of-experts model that activates only about 10B parameters per token. Every load size and speed in this guide co...
Kimi K3 VRAM Requirements (2026)
Kimi K3 needs about 1.4 TB of memory at the smallest quantization worth running, and 474 GB at the smallest file that exists. We read those numbers from the file listing of the community GGUF reposito...
Best LLM for Mac Studio M5 Max with 128GB RAM (2026)
The 128GB Mac Studio M5 Max is the maximum configuration of Apple's M5 Max desktop, announced August 26 and shipping September 22. It keeps the same 614 GB/s memory bus as the 48GB through 96GB tiers ...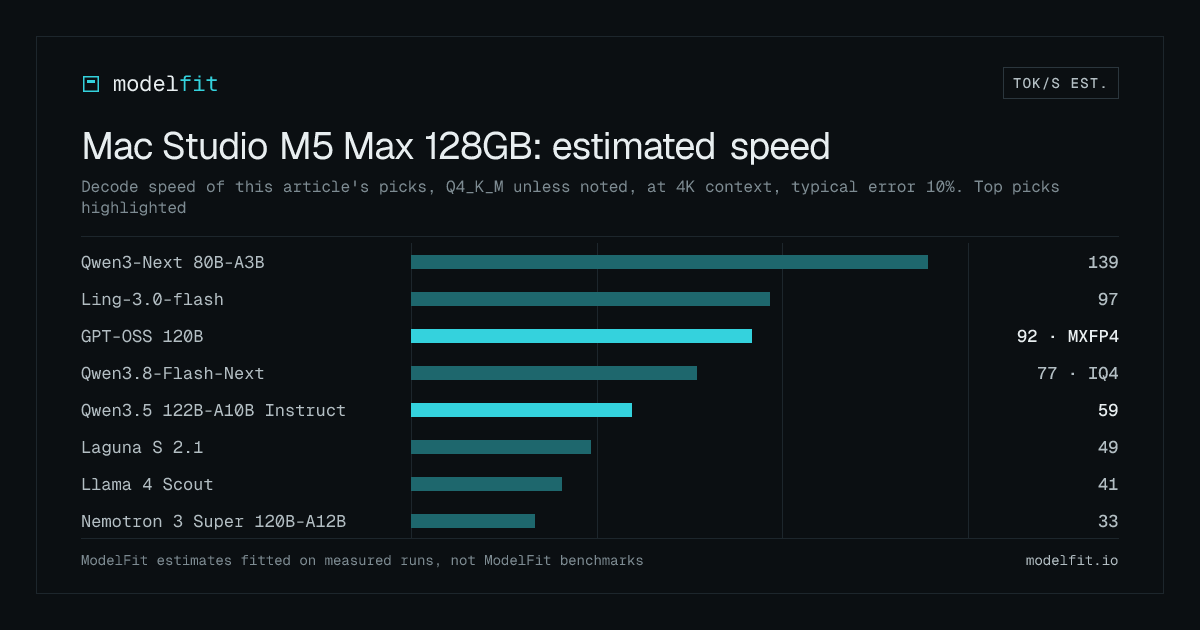
Best LLM for Mac Studio M5 Max with 36GB RAM (2026)
The 36GB Mac Studio M5 Max is the entry point into Apple's most powerful desktop for local AI in 2026. Announced on August 26 and shipping September 22, it starts at $2,499 with a binned 460 GB/s memo...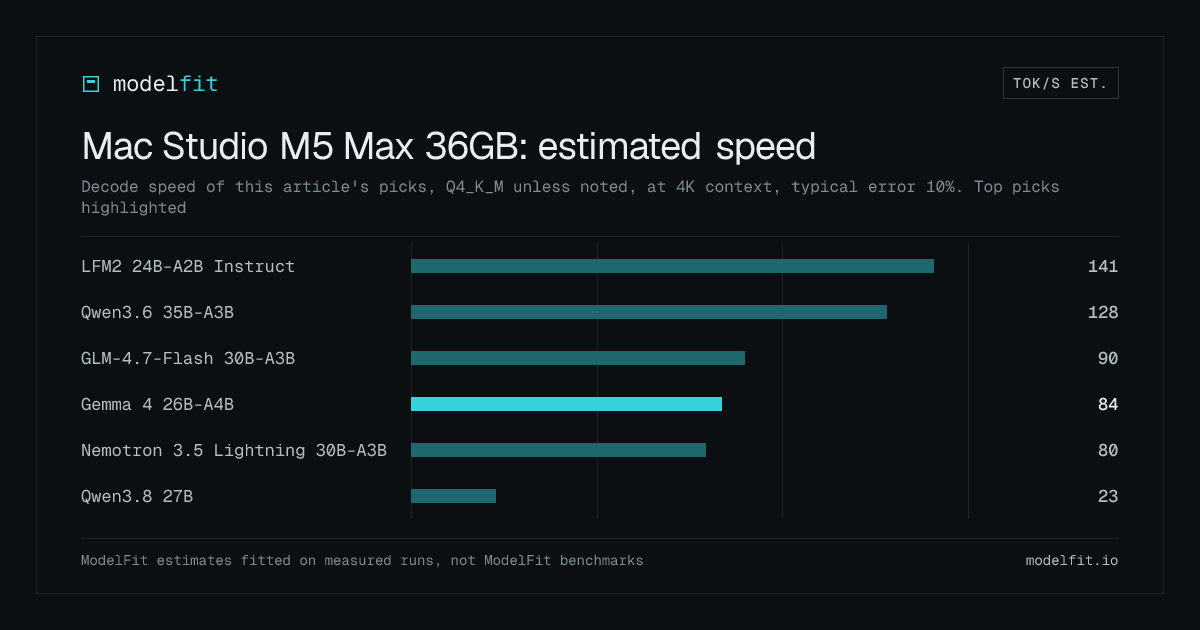
Best LLM for Mac Studio M5 Max with 48GB RAM (2026)
The 48GB Mac Studio M5 Max is the MoE sweet spot of the lineup. At 48GB with the full 614 GB/s memory bus, it unlocks the 35B MoE class with real context headroom. It starts at $2,499 for the base chi...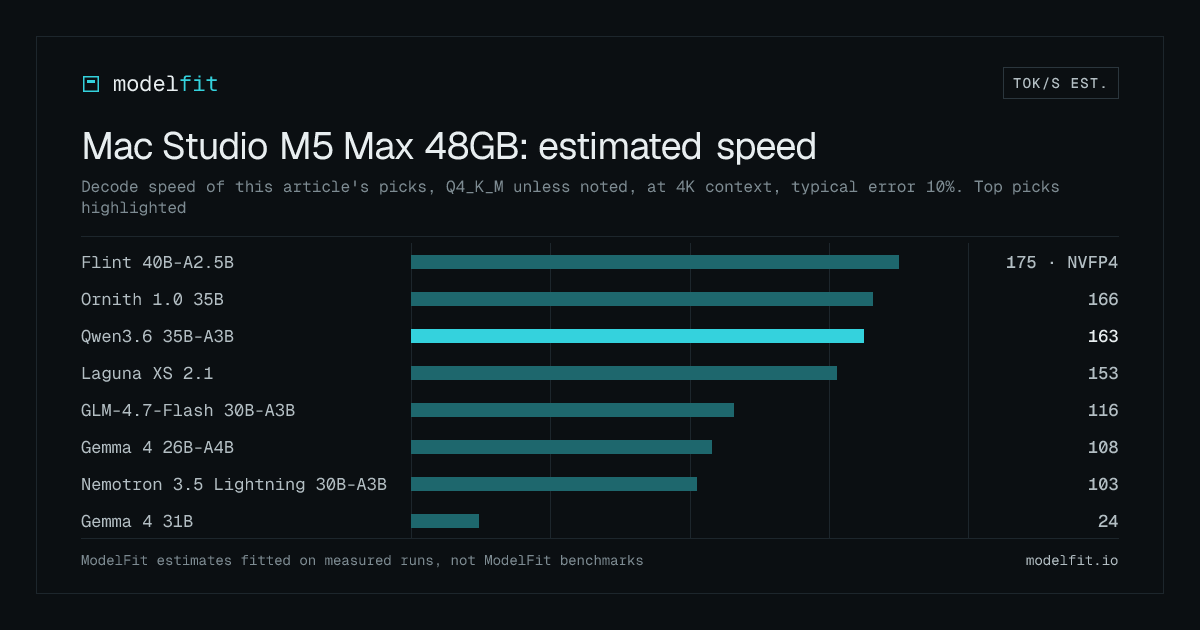
Best LLM for Mac Studio M5 Max with 64GB RAM (2026)
The 64GB Mac Studio M5 Max is the serious developer's desktop. With 64GB of unified memory and the full 614 GB/s bandwidth bus, it unlocks Q8 quantization for 35B MoE models, which preserves near-loss...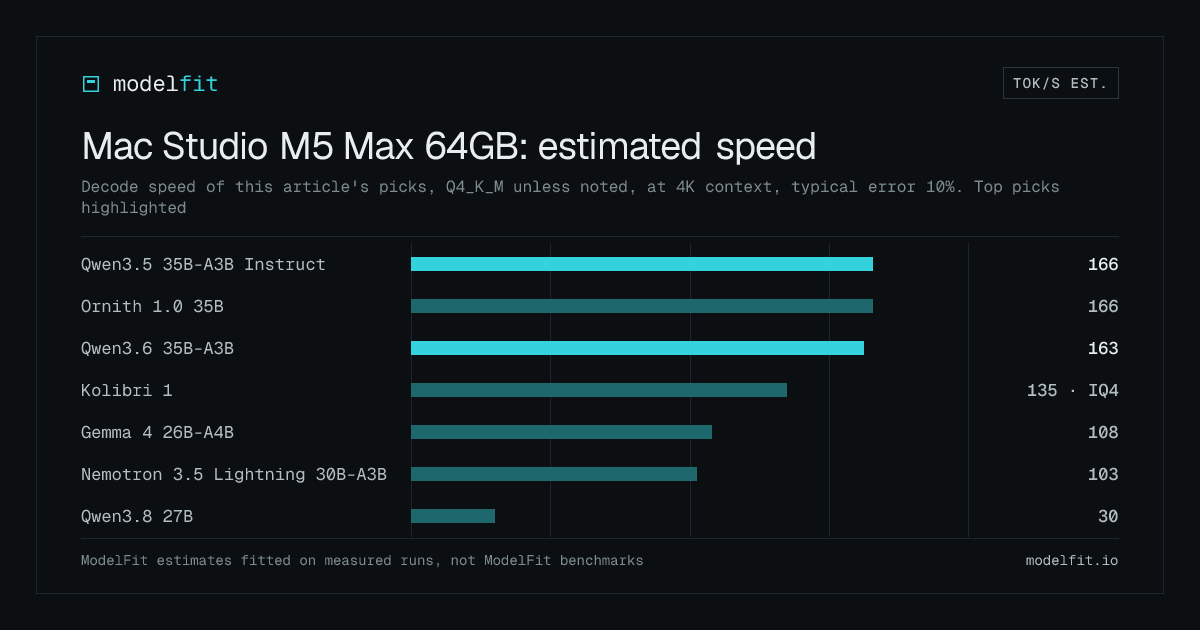
Best LLM for Mac Studio M5 Ultra with 256GB RAM (2026)
The Mac Studio M5 Ultra with 256GB unified memory, announced August 26, 2026, is the multi-model workstation. With 1.2 TB/s bandwidth - roughly 50% more than the M3 Ultra - and approximately 218GB usa...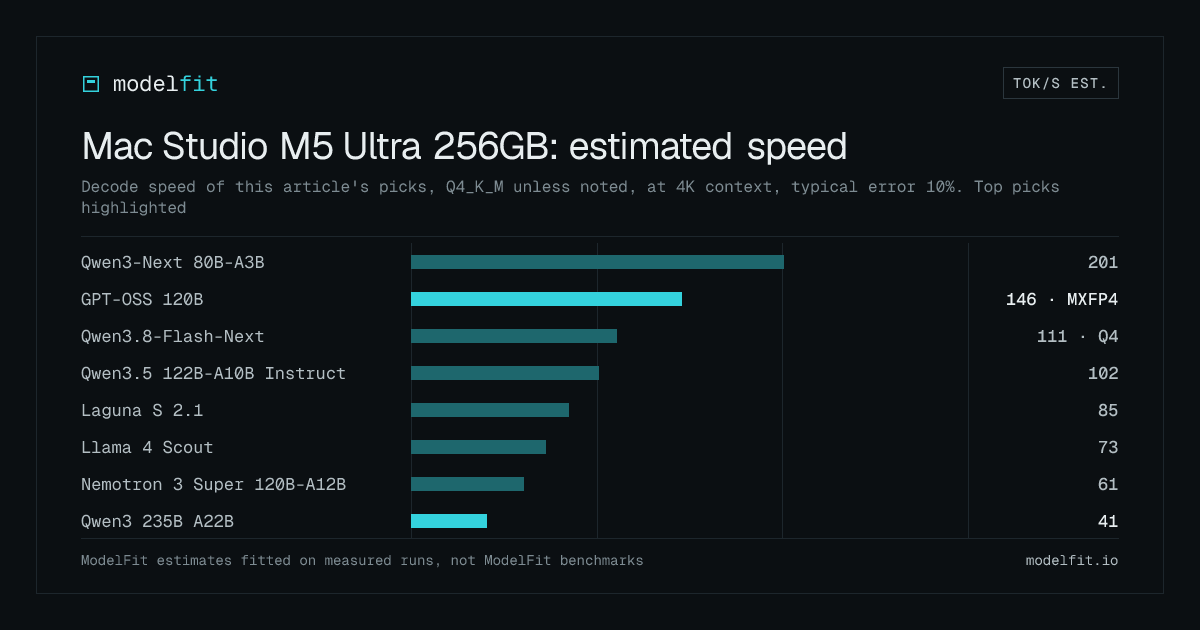
Best LLM for Mac Studio M5 Ultra with 512GB RAM (2026)
The Mac Studio M5 Ultra with 512GB unified memory is the most capable local AI machine Apple has ever sold. Announced August 26, 2026, shipping late October, it delivers 1.2 TB/s memory bandwidth and ...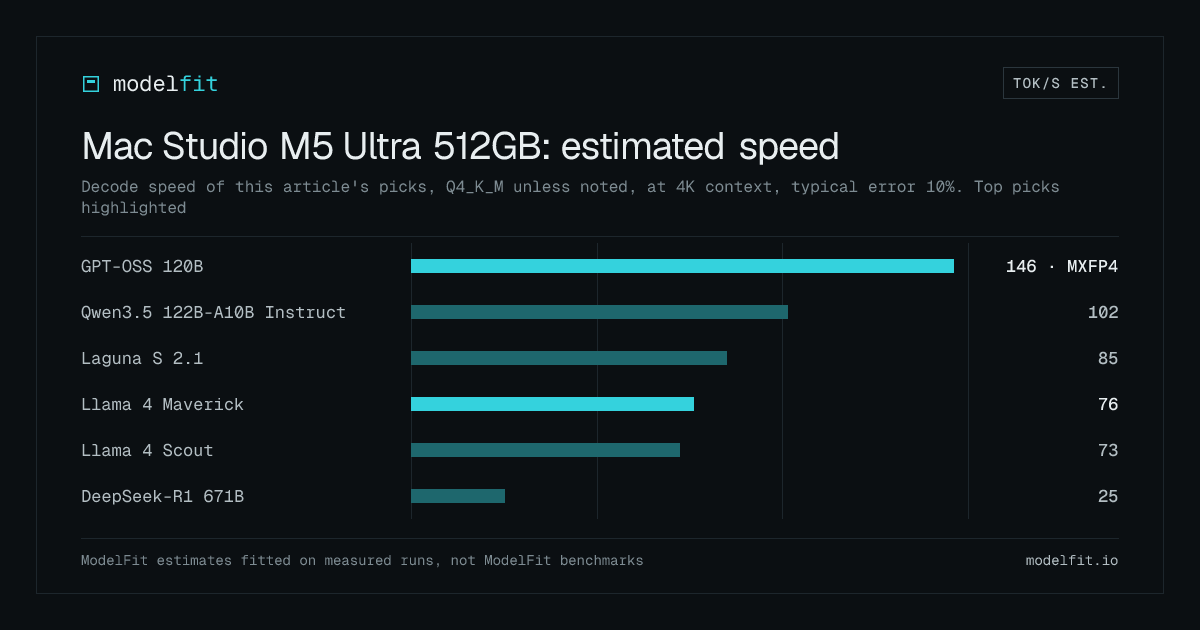
Best LLM for Mac Studio M5 Ultra with 96GB RAM (2026)
Apple announced the Mac Studio M5 Ultra on August 26, 2026, and the 96GB memory tier is where the Ultra line makes the most sense for most buyers. Starting at $5,499 with 1.2 TB/s of memory bandwidth,...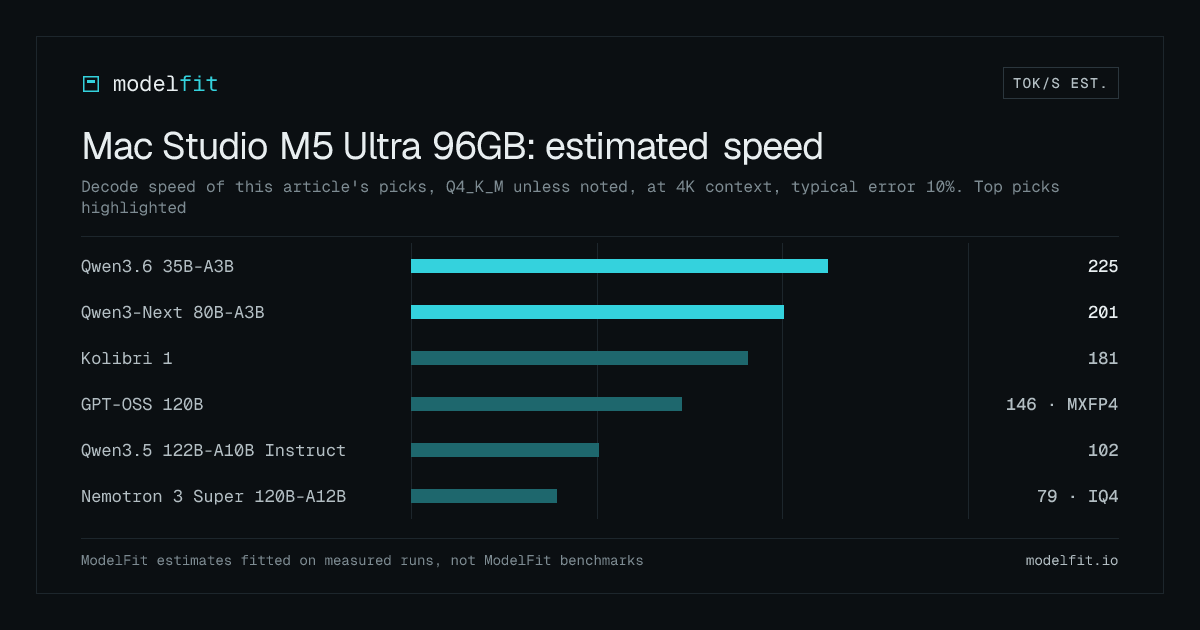
M5 Ultra vs M3 Ultra for Local LLMs: The 50% Bandwidth Jump
Apple announced the M5 Ultra Mac Studio on August 26, 2026, with shipping from September 22 for the 96GB and 256GB configurations and from late October 2026 for 512GB. For local LLM work, two numbers ...
Best LLM for Mac Mini M5 Pro with 48GB RAM (2026)
Apple announced the M5 Pro Mac Mini on August 26, 2026, with pre-orders opening same day and shipments starting September 22. The M5 Pro delivers 307 GB/s memory bandwidth, and the 48GB config starts ...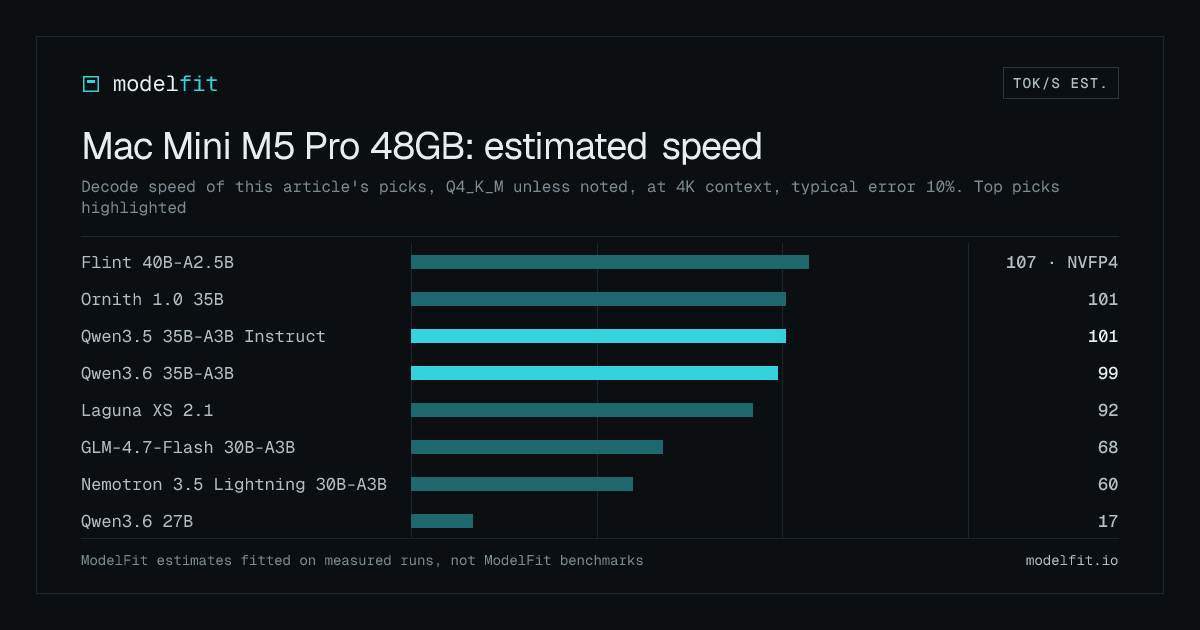
Best LLM for Mac Mini M5 Pro with 64GB RAM (2026)
Apple announced the M5 Pro Mac Mini on August 26, 2026, with pre-orders same day and shipments from September 22. The M5 Pro delivers 307 GB/s memory bandwidth, and the 64GB config is the highest RAM ...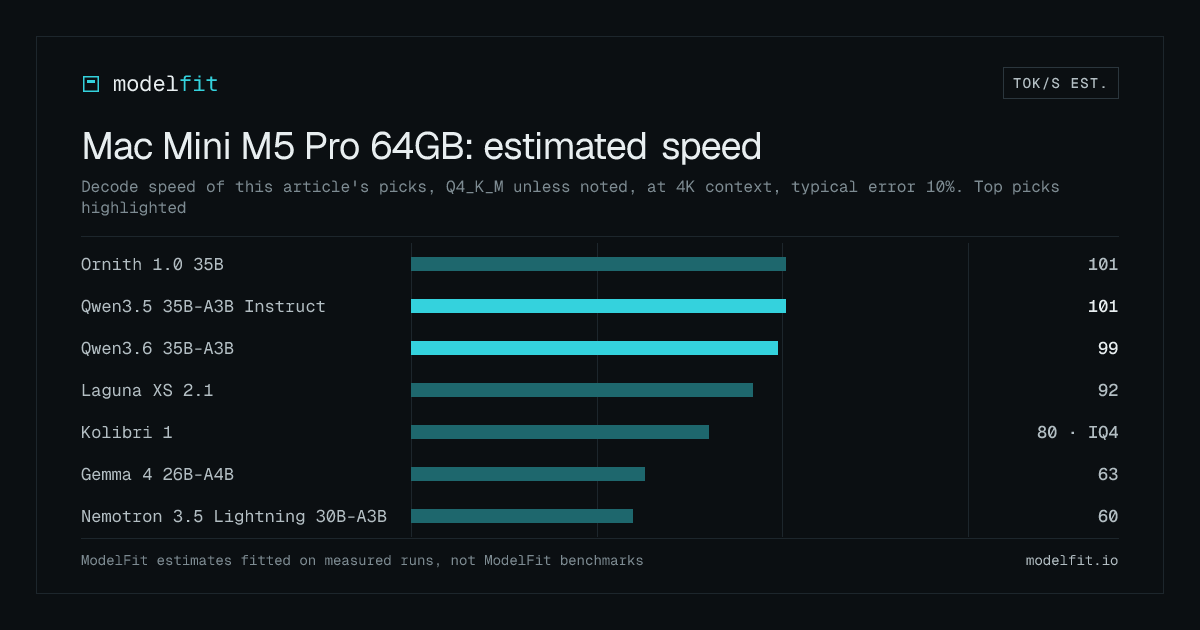
Best LLM for Mac Mini M6 with 16GB RAM (2026)
Apple announced the M6 Mac Mini on August 26, 2026, with pre-orders open the same day and shipping starting September 22. The base model pairs a 12-core CPU and 12-core GPU with 16GB of unified memory...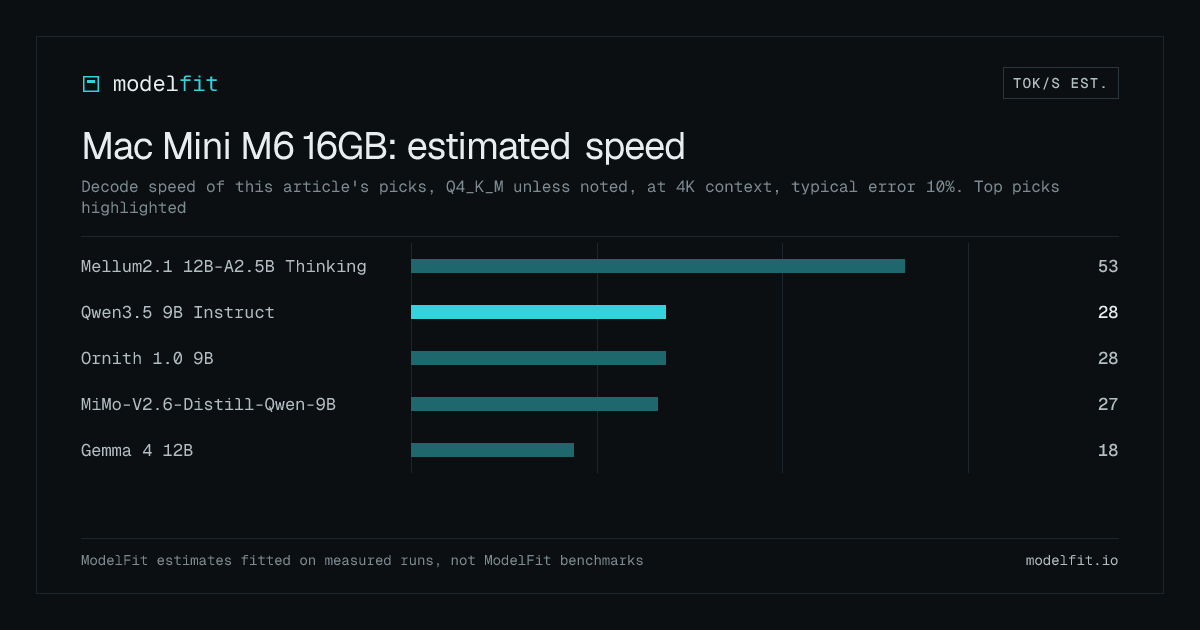
Best LLM for Mac Mini M6 with 24GB RAM (2026)
Apple announced the M6 Mac Mini on August 26, 2026, with pre-orders open the same day and shipping starting September 22. The 24GB config pairs a 12-core CPU and 12-core GPU with 170 GB/s of unified m...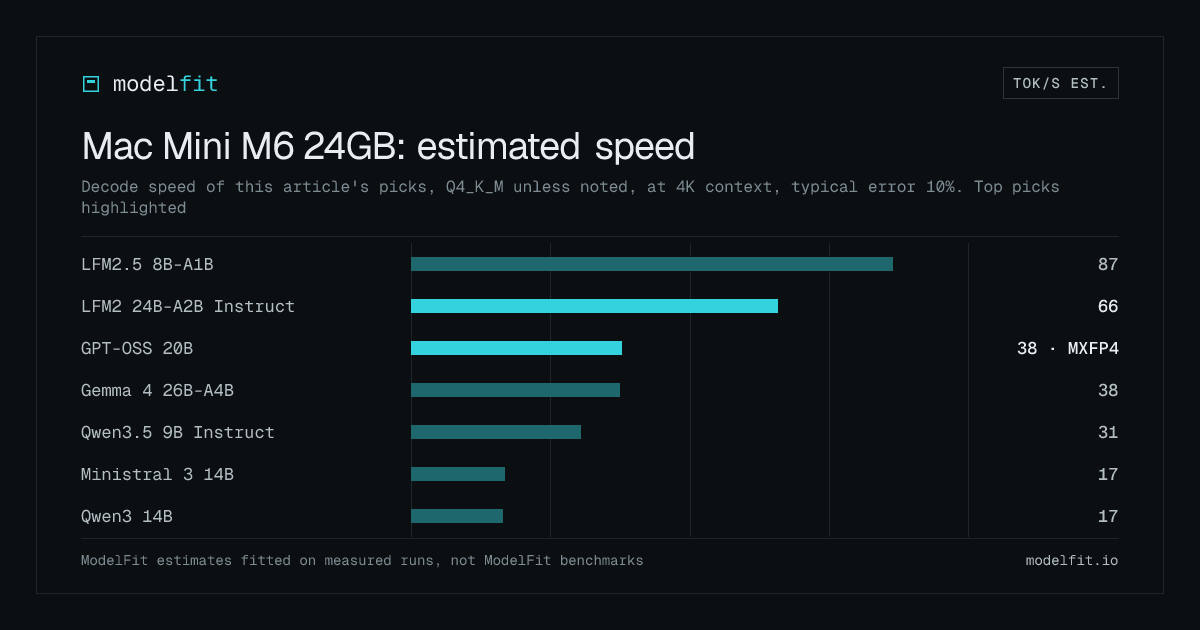
Best LLM for Mac Mini M6 with 32GB RAM (2026)
Apple announced the M6 Mac Mini on August 26, 2026, with pre-orders open the same day and shipping starting September 22. The 32GB config is the top M6 RAM tier, pairing a 12-core CPU and 12-core GPU ...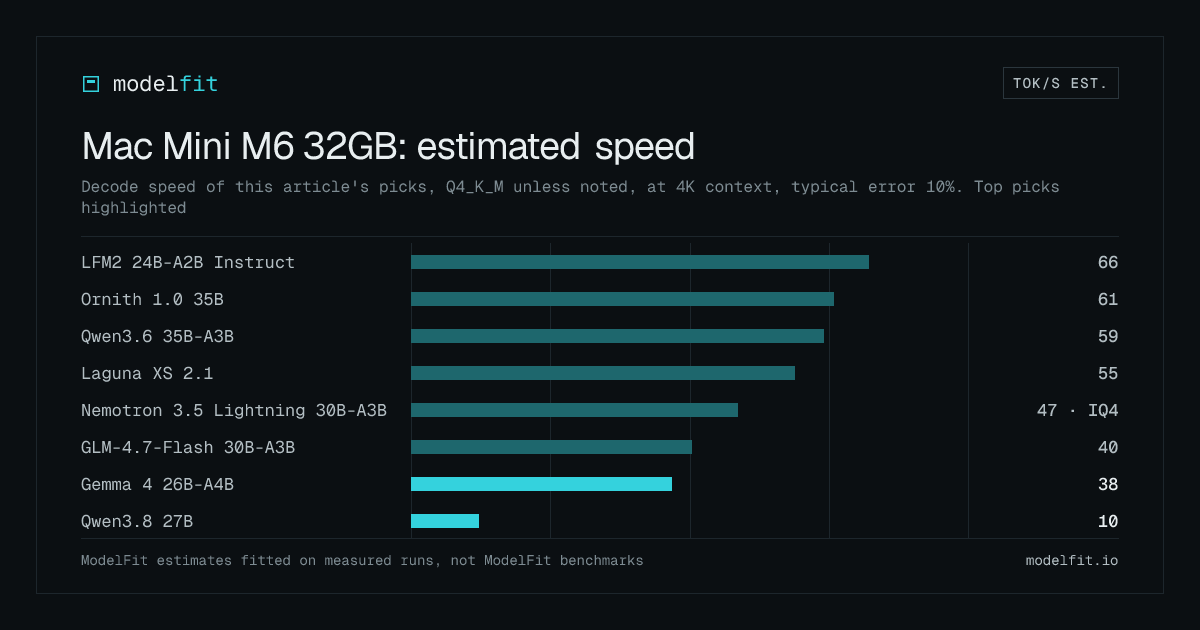
M6 Mac Mini for Local AI: What the 2026 Base Mac Runs (16-32GB)
Apple announced the M6 Mac Mini on August 26, 2026, with shipping on September 22. The base config pairs a 12-core CPU and 12-core GPU with 16GB of unified memory at 153 GB/s for $899, and the 24GB/32...
Mac Studio M5 Ultra 512GB: Every Local LLM It Runs (2026)
Apple announced the M5 Ultra Mac Studio on August 26, 2026, with pre-orders open today. The 96GB and 256GB configurations ship from September 22, and the 512GB configuration ships from late October 20...
Qwen3.8-Flash-Next: Specs, Benchmarks and Mac Speeds (2026)
Qwen released Qwen3.8-Flash-Next on August 26, 2026, and it is not a normal point release. It is the first open-weight model built on the architecture that will underpin Qwen4: a 125B mixture-of-exper...
Qwen3.8 vs Nemotron 3.5 vs Muse Glimmer: Best 30B Agent (2026)
The week of August 10, 2026, turned the local agent market into a three-way race. Meta shipped Muse Glimmer, a 30B model built for always-on local agents (Ollama library, 2026). NVIDIA shipped Nemotro...
Run Qwen3.8-27B Locally: 24GB Mac and GPU Guide (2026)
Qwen released Qwen3.8-27B in mid-August 2026, and the community adopted it fast. The unsloth GGUF passed 1,945,635 downloads in about three days (HuggingFace API, 2026). The model is a dense 27B visio...
DeepSeek-V4-Flash 0731: 284B Agent Fits a 128GB MacBook
DeepSeek released DeepSeek-V4-Flash-0731 on July 31, 2026, the official version of its 284B-parameter agentic model, and the community quant ladder puts it on consumer hardware. The 2-bit DQ MLX build...
Inkling Small on Mac Studio: An 80.2 SWE-Bench Open Model That Fits
Thinking Machines' Inkling Small is the highest-scoring open-weight model on SWE-bench Verified and the first frontier-class model that fits a Mac Studio. It scores 80.2% on SWE-bench Verified (model ...
Run DeepSeek-V4-Flash Locally: Hardware You Need (2026)
The cheapest new machine that runs DeepSeek-V4-Flash locally is a 128GB AMD Ryzen AI Max+ 395 mini PC. The Apple path is a 128GB MacBook Pro with the M5 Max. The single GPU with almost enough VRAM, th...
Kimi K3 Weights Are Out: What It Takes to Run Them (2026)
Moonshot published the Kimi K3 weights on July 27, 2026, and the honest answer changed. No Mac and no GPU runs this model: the smallest community quant on HuggingFace is 567GB, which is 55GB more than...
Ornith 1.0 9B: A 5.6GB Coder That Rivals 35B Models (2026)
Deep Reinforce released Ornith 1.0, and the 9B member reports 69.4 on SWE-bench Verified against 70 for Qwen3.5-35B, a model roughly four times its size (Ornith-1.0-9B model card, 2026). It pulls in 5...
Qwen3.8-Max Is 2.4T: What Open Weights Would Cost You (2026)
Alibaba previewed Qwen3.8-Max on July 19, 2026, a 2.4 trillion parameter multimodal model it describes as second only to Fable 5, and said open weights are coming with no date attached (MarkTechPost, ...
M5 Pro 24GB vs 48GB for Local LLMs: The $400 Question
For local AI, yes: pay the $400. Going from 24GB to 48GB on the 14-inch MacBook Pro M5 Pro is a $400 upgrade (9to5Mac, 2026), and it roughly doubles your usable model budget, from about 17GB to about ...
RAM Prices in 2026: What the Shortage Means for Local AI
RAM is the single input that decides which local AI models you can run, and it has never been more expensive. Conventional DRAM contract prices jumped 93% to 98% in Q1 2026 alone (TrendForce, 2026), a...
The 64GB Mac Dead Zone for Local LLMs (2026)
The local AI community calls 64GB Macs a dead zone, and the math backs half of it. A 70B model at Q4 weighs 43GB on disk (Ollama registry), a 64GB Mac gives a model roughly 48GB to work with, and 32k ...
How Far Behind Cloud AI Is Your Laptop? (2026)
Somewhere between 4 and 25 months, and the honest answer for laptop hardware is close to 11. A chart claiming laptop-runnable AI trails the cloud frontier by an average of 24.8 months went viral on r/...
Run a 744B Model on 25GB RAM? The Honest Math (2026)
Yes, a 744B-parameter model can run on a machine with 25GB of RAM. A new open-source engine called colibri does it by streaming GLM-5.2's experts from an NVMe drive, and it earned over 1,200 GitHub st...
Mac Mini for Local AI: Buy M4 Now or Wait for M5? (2026)
> TL;DR: Buy the Mac Mini M4 now if you need a local AI machine this year. The entry price already jumped from $599 to $799 (Bloomberg, 2026), memory prices are still climbing, and the M5 mini is only...
Apple M7 for Local AI: Roadmap and What to Run Now (2026)
> TL;DR: Apple is reportedly fast-tracking the M7 chip, moving its release up by about half a year, with a rumored base memory bandwidth near 240 GB/s, a 57% jump over the M5's confirmed 153 GB/s. Non...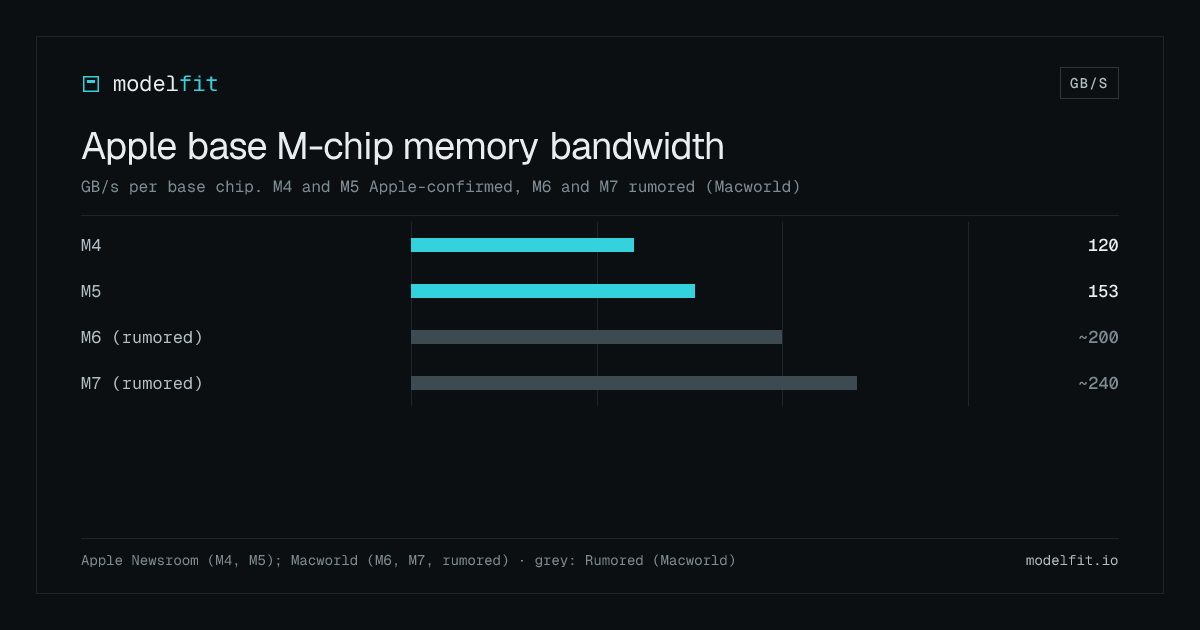
Which Bottleneck Are You Buying? Local AI Hardware Guide (2026)
> TL;DR: Local AI hardware comes down to three things: memory capacity (what fits), memory bandwidth (how fast it answers), and software stack maturity (how much of the spec you actually get). Vendor ...
Gemma 4 12B: Best Local LLM for 16GB RAM (2026)
> TL;DR: Gemma 4 12B is Google's dense, Apache 2.0 model that fits a 16GB Mac or 8-12GB GPU at its default 7.6GB quant (ollama run gemma4:12b). It scores 77.2% on MMLU Pro and beats last year's Gemma ...
Local LLM Refresh: A Coding Wave Hits Ollama (June 2026)
> TL;DR: Three 30B-class Mixture-of-Experts models with about 3B active parameters landed on Ollama this fortnight: Cohere's North Mini Code and Poolside's Laguna XS.2 (both coding-focused, Apache 2.0...PewDiePie's Odysseus: Why It Matters for Local AI (2026)
> TL;DR: PewDiePie released Odysseus, a free, self-hosted AI workspace under AGPL-3.0 that passed 74,000 GitHub stars in about three weeks. It runs on any hardware, not just his own 424GB, 10-GPU rig....
Best LLM for MacBook Air M2 16GB: 5 Models Ranked (2026)
> TL;DR: The MacBook Air M2 with 16GB RAM comfortably runs models up to ~14B parameters at Q4. Qwen3.5 9B tops ModelFit's ranking as the best all-rounder: ~7GB loaded, native multimodal, near-frontier...AMD Strix Halo 128GB Local AI (2026): Specs, Speed, Price
> TL;DR: The AMD Ryzen AI Max+ 395 ("Strix Halo") puts 128GB of unified memory in a mini PC, letting it load models up to ~200 billion parameters locally, something no consumer GPU can do. On Linux it...
Local LLM Weekly: Gemma 4 12B Hits Ollama (June 2026)
> TL;DR: Gemma 4 12B is the week's standout local release: a 16GB-friendly multimodal model (ollama run gemma4:12b) scoring 77.2 on MMLU-Pro. Six cloud-only flagships also shipped, including Anthropic...Best LLM for MacBook Air M5 16GB: 5 Models Ranked (2026)
> TL;DR: The MacBook Air M5 with 16GB RAM runs the same ~14B-parameter ceiling as the M4 Air, but its 153 GB/s memory bandwidth (a 28% jump over the M4's 120 GB/s, per Apple) makes every model faster....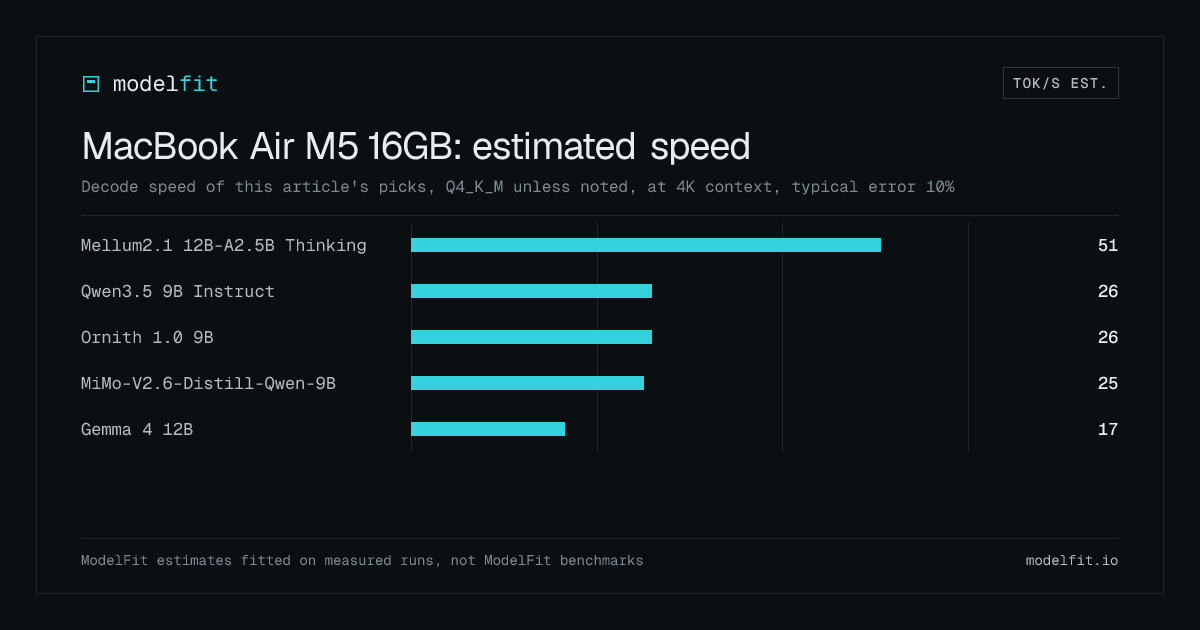
MLX vs Ollama on Mac (2026): Which Runtime Is Fastest?
> TL;DR: On Apple Silicon, MLX-based runtimes now beat the old llama.cpp path by roughly 1.4x on dense models and up to 3x on mixture-of-experts models. Ollama 0.19 (March 2026) switched to MLX itself...
Does Speculative Decoding Speed Up Local LLMs on Mac? (2026)
> TL;DR: Speculative decoding lets a model draft several tokens and verify them in one pass, 2x or more faster, with identical output. But on a Mac the framework decides everything. With llama.cpp on ...
How We Scored 100/100 on Agent-Readiness (2026)
> TL;DR: ModelFit scored a perfect 100/100, Level 5 "Agent-Native" on isitagentready.com, up from 27 before we started. We passed 14/14 checks across four scored categories by shipping the emerging ag...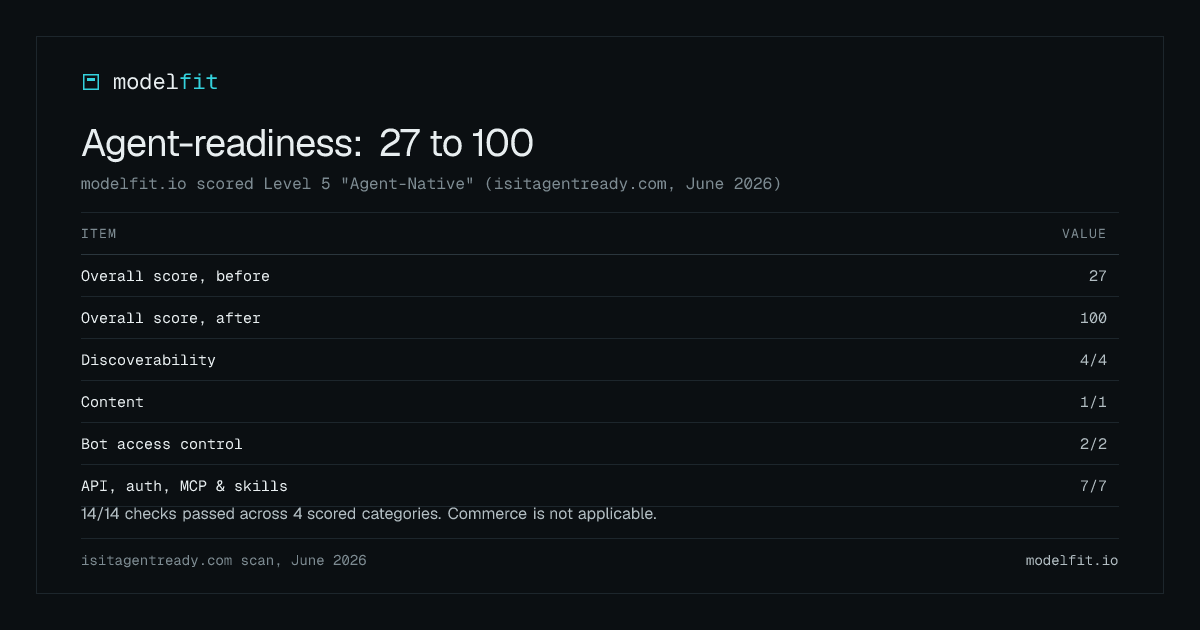
Run a Local LLM on Mac With No Terminal (2026)
> TL;DR: LM Studio is a free desktop app that runs local LLMs with a ChatGPT-style chat window, a one-click model browser, and built-in Metal acceleration, no terminal required. Install it, pick a mod...Qwen 3.6 on Mac: The 17GB Coder Scoring 77.2 (2026)
> TL;DR: Qwen 3.6 27B scores 77.2 on SWE-Bench Verified (Qwen3.6-27B card, 2026) and downloads at ~17GB on Ollama, so it fits a 32GB Mac. The MoE sibling, 35B-A3B, activates only 3B params per token, ...Should You Run IBM Granite 4.1 (3B / 8B) Locally on Your Mac?
IBM shipped Granite 4.1 in early June 2026, a full refresh of its open-weight lineup. The family includes dense decoder-only models at 3B, 8B, and 30B, all Apache 2.0 licensed and trained on roughly 1...LFM2.5 on Mac: Run Liquid AI's Fastest Local Model with Ollama (2026)
Liquid AI shipped LFM2.5 in early 2026, and the 8B-A1B variant is the sweet spot for Apple Silicon. It packs 8.3 billion total parameters but activates only 1.5 billion per token. That means MacBook A...Best LLMs for Mac Mini M4 16GB RAM: Top 5 Ranked (2026)
> TL;DR: The Mac Mini M4 with 16GB RAM runs models up to ~13B parameters at Q4 quantization without breaking a sweat. Qwen3.5 9B ranks first and is the best daily driver: near-frontier quality in ~7GB...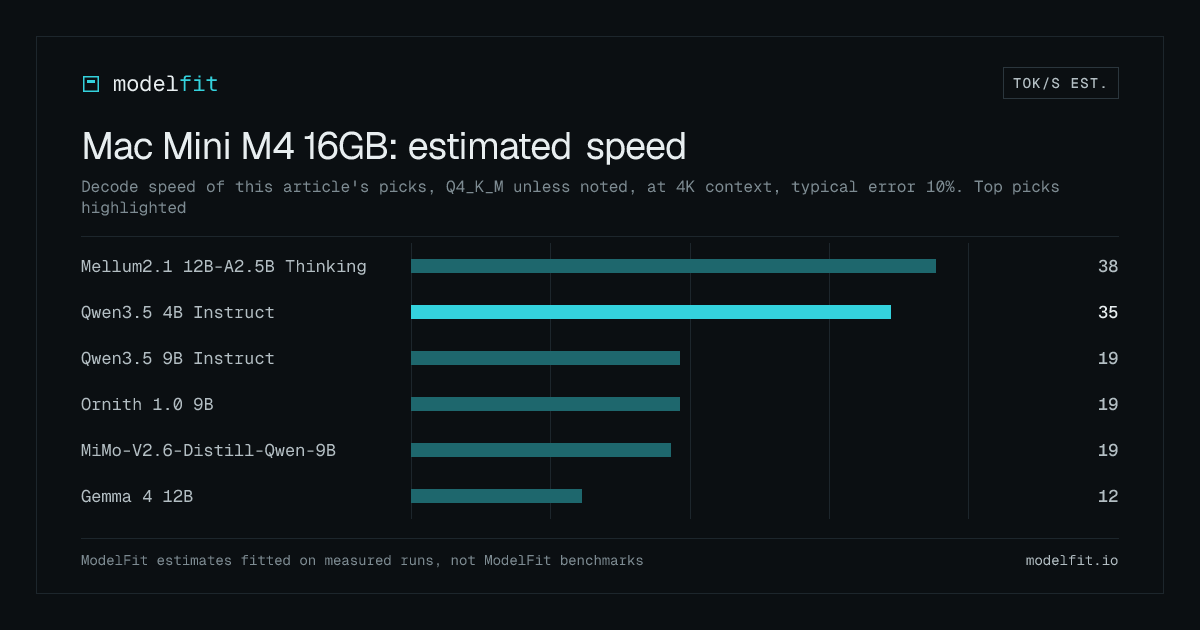
Best LLMs for Mac Mini M4 24GB RAM: Top 6 Ranked (2026)
> TL;DR: The Mac Mini M4 with 24GB RAM runs models up to ~20B parameters at Q4 quantization cleanly, and squeezes 27B at a tight fit, with Qwen3.8 27B now the top quality pick at ~17.8GB. GPT-OSS 20B ...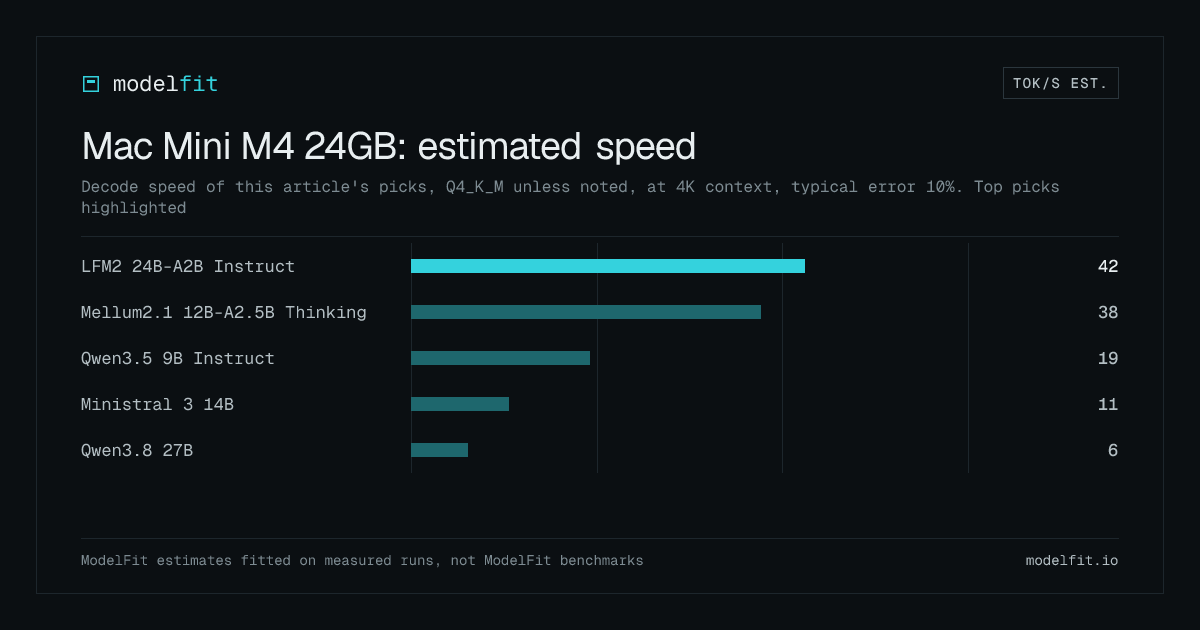
Best LLM for MacBook Air M4 16GB: 5 Models Ranked (2026)
> TL;DR: The MacBook Air M4 with 16GB RAM can comfortably run models up to ~14B parameters at Q4 quantization. Qwen3.5 9B tops ModelFit's ranking as the best all-rounder: it fits in ~7GB, ships native...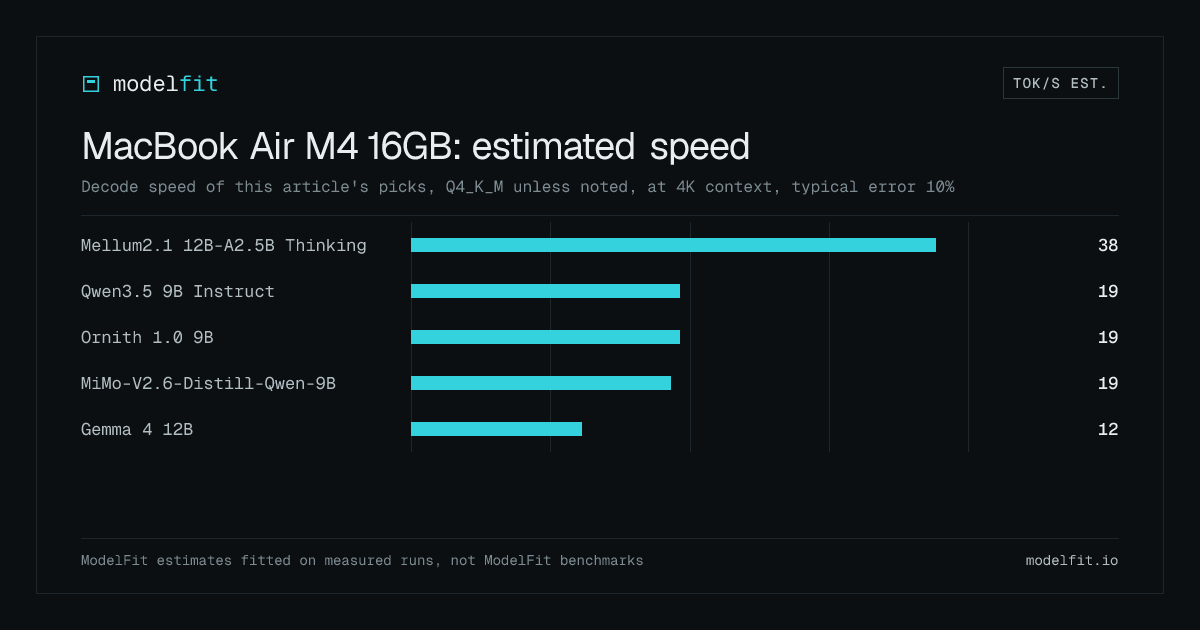
Best LLM for MacBook Air M4 24GB: 6 Models Ranked (2026)
> TL;DR: The MacBook Air M4 with 24GB RAM runs models up to ~20B parameters at Q4 quantization, and pushes to qwen3.8:27b at a tight fit, the new 27B quality leader with native vision. Qwen3.5 9B is t...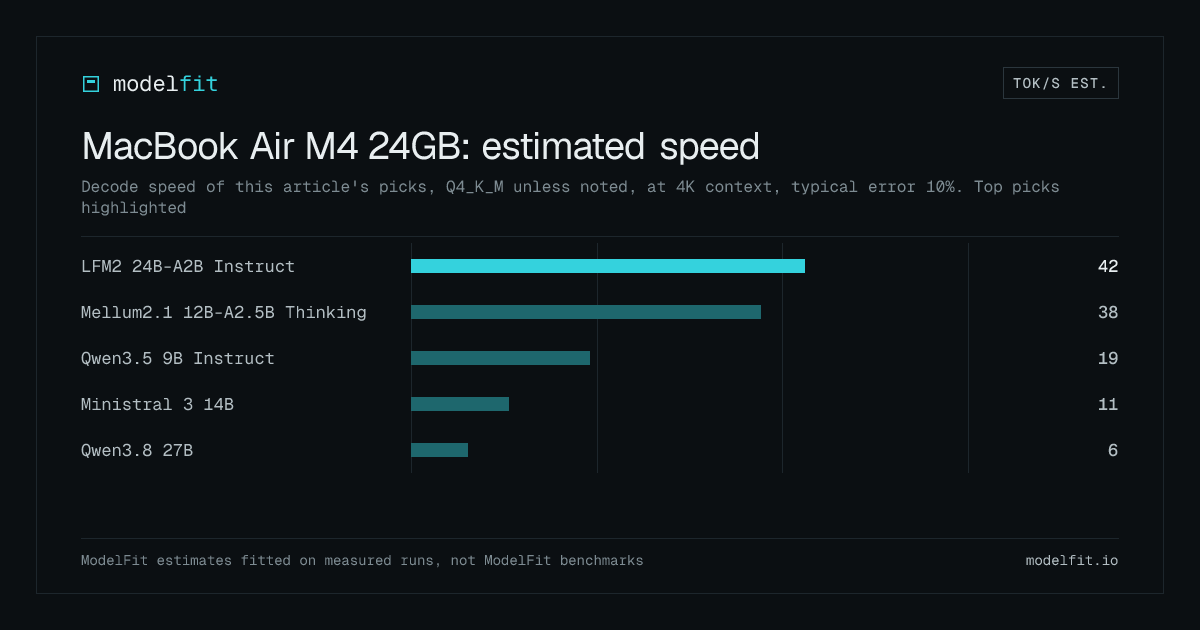
Best LLM for MacBook Pro M4 Max 64GB (2026)
> TL;DR: The MacBook Pro M4 Max with 64GB RAM is a 70B-capable laptop. Qwen3.8 27B is the quality pick at ~25 tok/s (est.), fitting in ~17GB. Qwen3.6 35B-A3B delivers near-flagship reasoning at small-...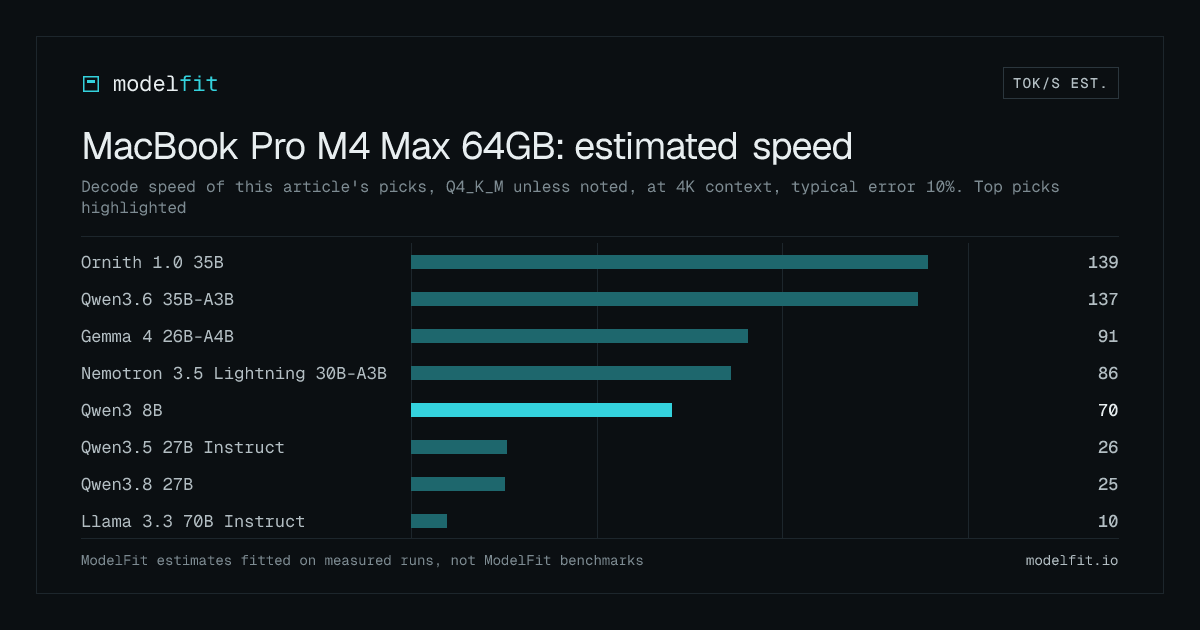
Best LLM for MacBook Pro M4 Pro with 24GB RAM (2026)
> TL;DR: The MacBook Pro M4 Pro with 24GB RAM is one of the best local AI machines you can buy. GPT-OSS 20B is the best daily driver: OpenAI's open-weight MoE, 21B-class knowledge at an estimated 53 t...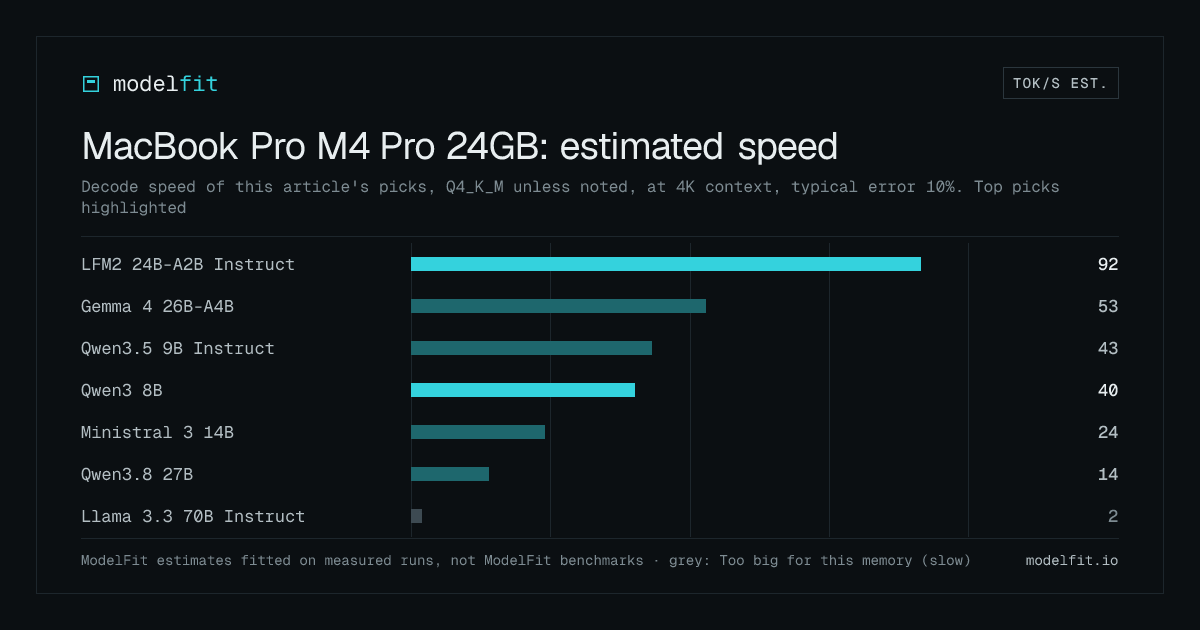
Qwen on Mac (2026): Best Model for 16GB, 24GB, 32GB RAM
> TL;DR: On a 24GB Mac, run Qwen 3.8 27B (ollama run qwen3.8:27b), Qwen's dense August 2026 model with vision. Qwen's model card reports 73.0 on Terminal Bench 2.1 and 61.7 on SWE-bench Pro. It is a t...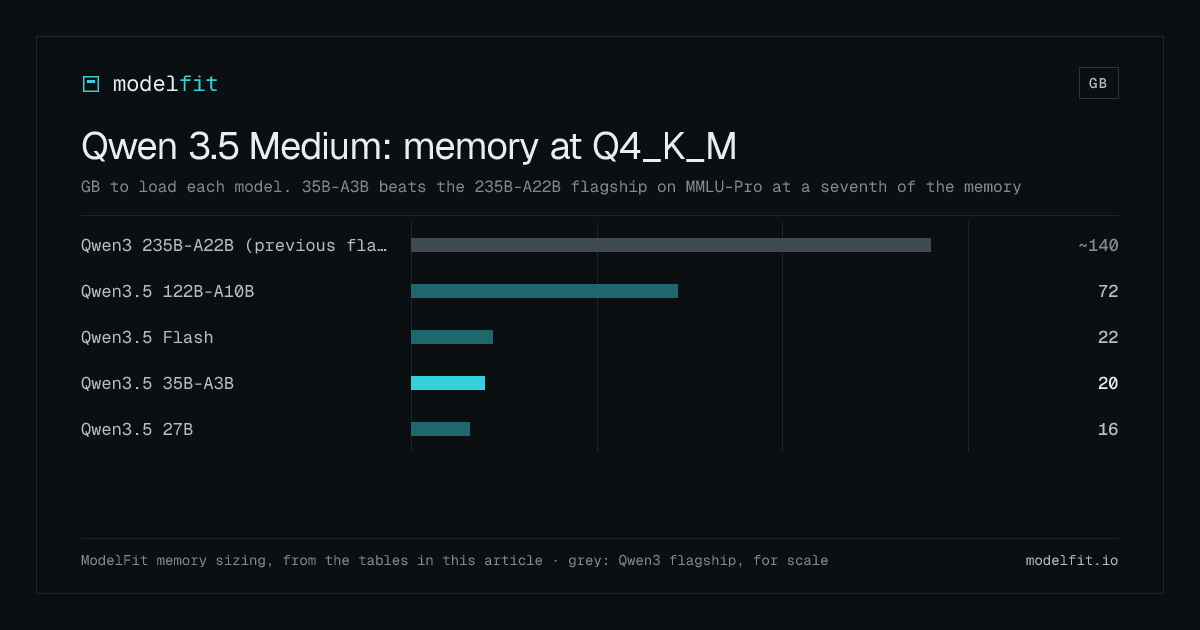
Best Local AI Coder for Mac: Qwen3.6 vs Gemma 4 (2026)
> TL;DR: Qwen3.6-35B-A3B is the best local coder for Mac: 73.4 on SWE-bench Verified with only 3B active parameters, fitting a 24GB Apple Silicon machine. Gemma 4 31B matches it on knowledge (85.2 MML...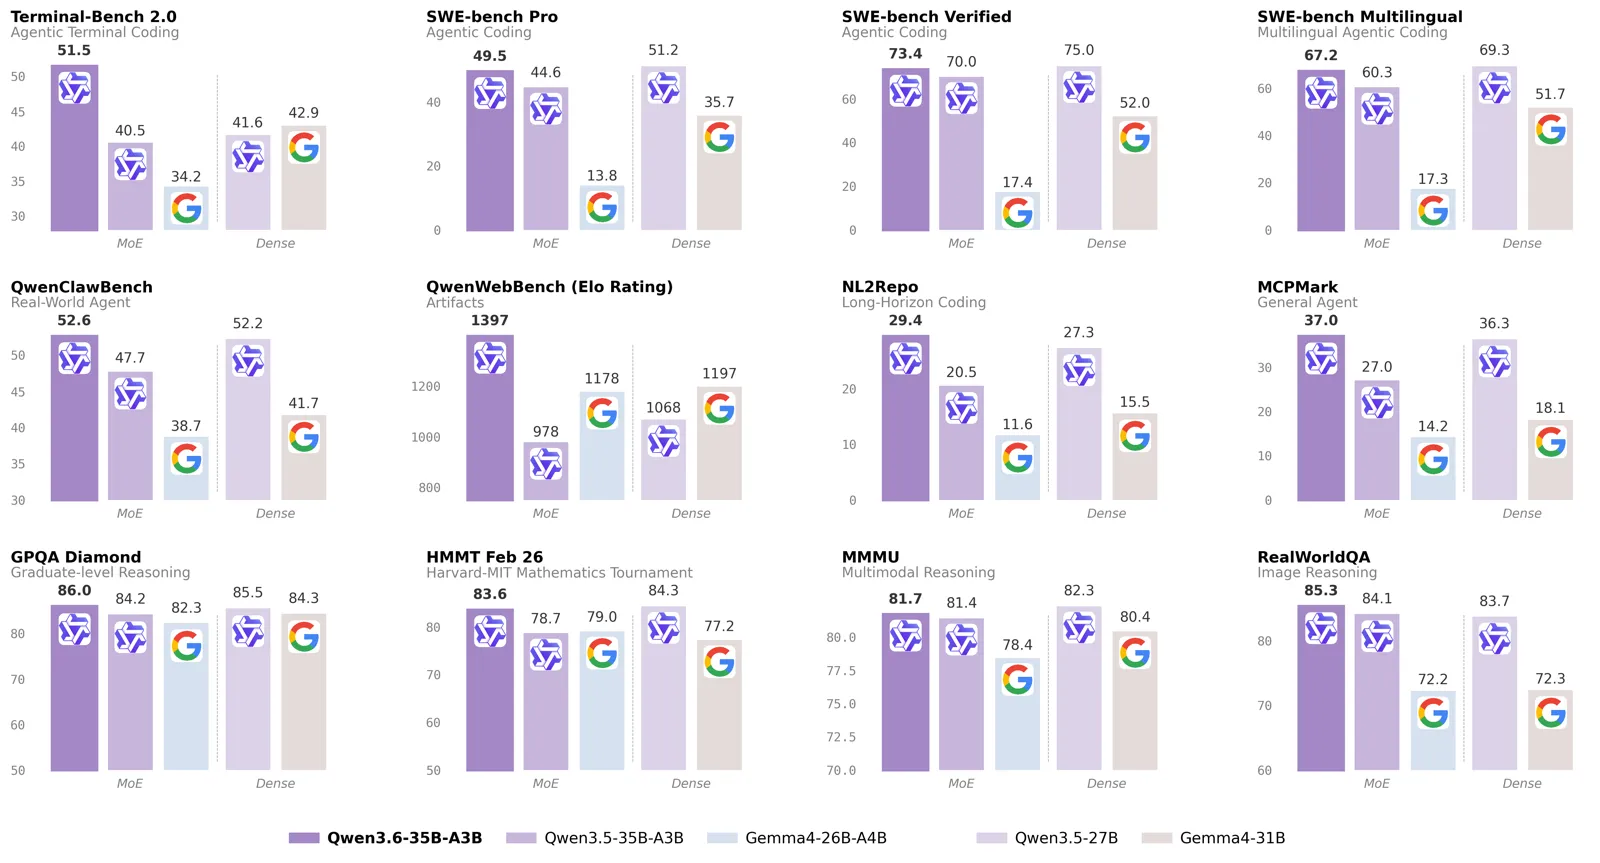
Run a 35B LLM on an Entry Mac Mini M4 (16GB): The mmap Trick
> TL;DR: A base Mac Mini M4 with 16 GB RAM can run Qwen3.5-35B-A3B at 17.3 tok/s with zero swap, per one documented independent test using llama.cpp's --mmap flag (source). The model is a Mixture-of-E...
Run Gemma on iPhone: Google AI Edge Gallery Guide (2026)
> TL;DR: Google AI Edge Gallery is a free Apple App Store app that runs Gemma 4 E2B (~2.5 GB) and E4B (~5 GB) fully on-device on iPhone. Reported speeds: an estimated ~30 tok/s on iPhone 16 Pro, ~12 t...Run Claude Code Free: Ollama Local Setup in 4 Steps (2026)
Claude Code is Anthropic's AI coding agent, and you can run it locally with Ollama instead of paying $100/month for Claude Max. Since Ollama v0.14 shipped native Anthropic Messages API compatibility i...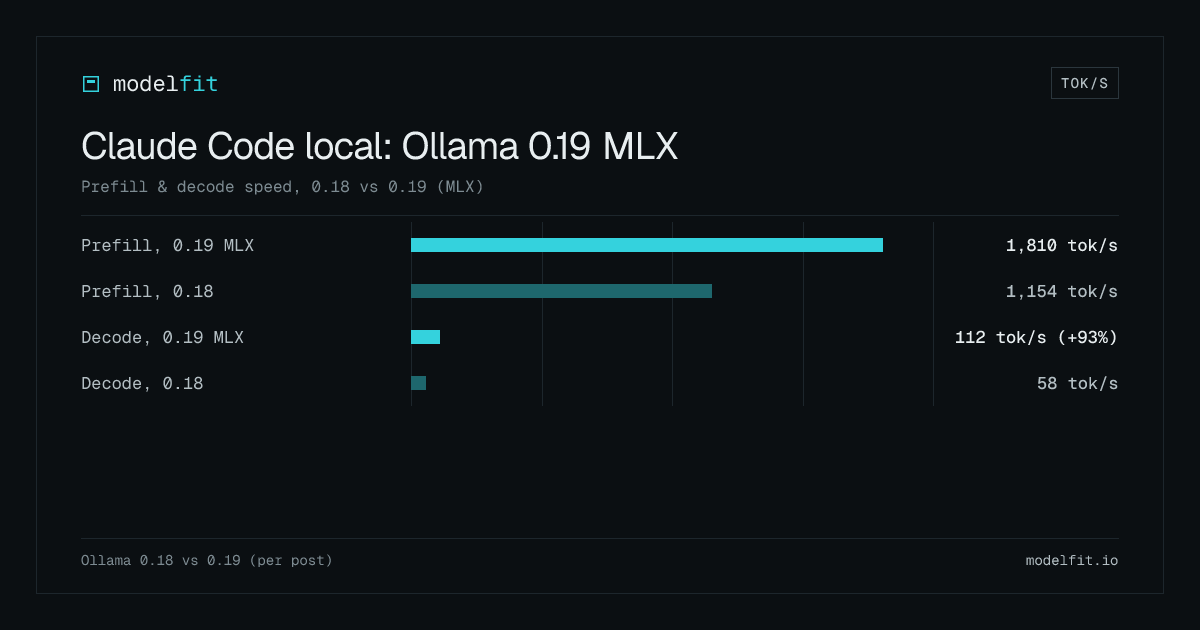
LFM2 + LocalCowork: Offline AI Agent for Mac (2026)
Liquid AI just shipped a working on-device AI agent, not a demo, a real one. LFM2-24B-A2B paired with LocalCowork runs 75 MCP tools entirely on your Mac: security scanning, file operations, audit logs...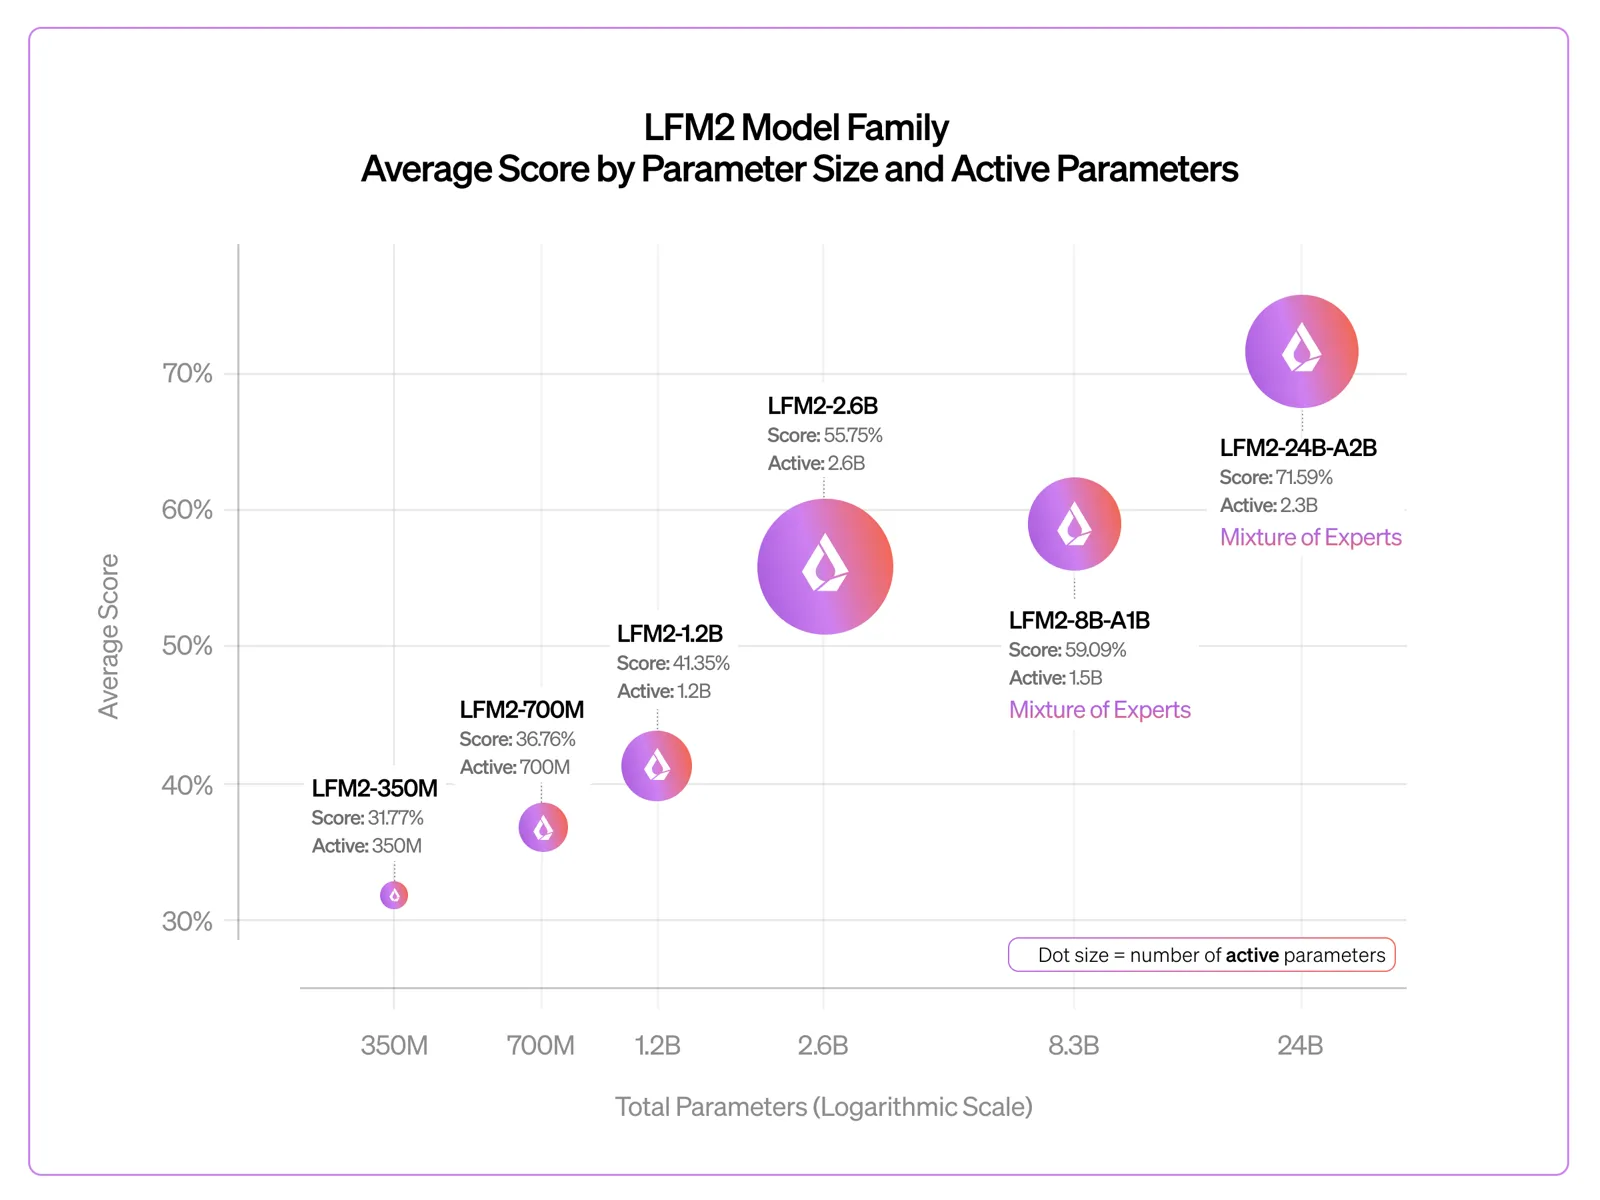
DeepSeek V4 Is Coming: What Mac Users Need to Know (2026)
> Update (May 2026): DeepSeek V4 has since shipped. The official DeepSeek-V4-Pro model card now lists 80.6% on SWE-Bench Verified, confirming the pre-release leaks were in the right range. See our loc...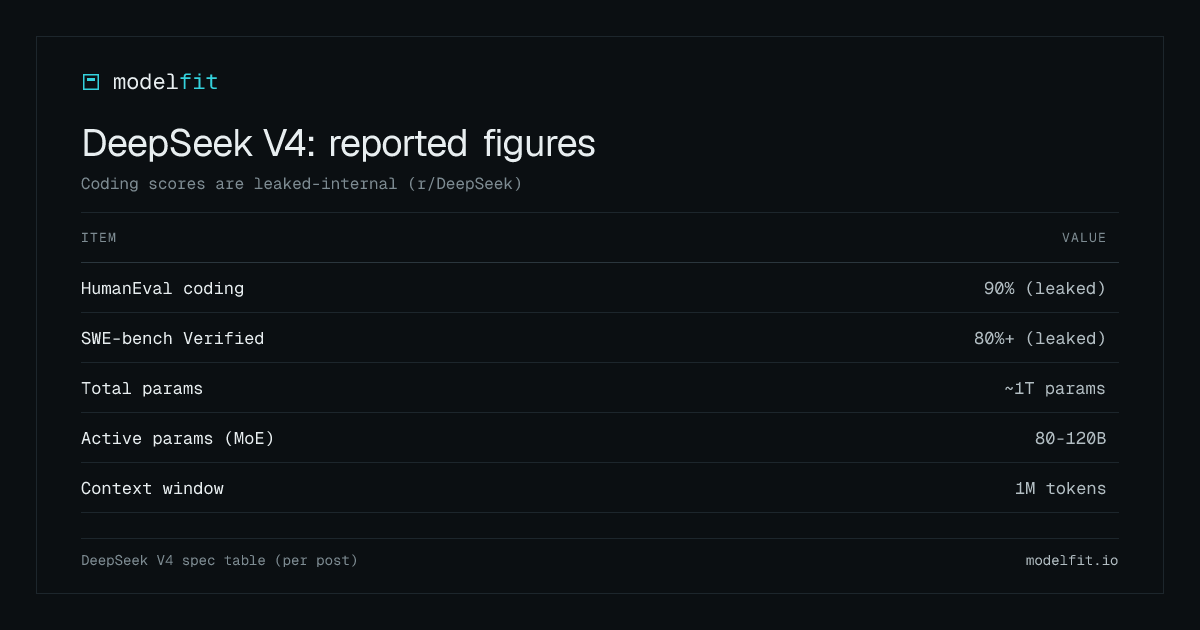
Mac Mini for Local AI: The Best Value Setup in 2026
> TL;DR: The Mac Mini M4 Pro with 64GB ($1,999-$2,499) is the best value local AI machine in 2026. It runs 30B-class models at an estimated 12-18 tok/s, costs ~$25/year in electricity, and gives every...Apple Core AI Framework: Core ML Replacement Coming at WWDC 2026
Apple is replacing Core ML with a brand-new framework called Core AI, set to debut at WWDC 2026 this June. The rename from "Machine Learning" to "AI" isn't cosmetic; it signals a fundamental shift in ...LLMfit (2026): Install, Commands, and a No-Install Online Option
> TL;DR: LLMfit is a Rust CLI that detects your RAM, CPU, and GPU, then scores 200+ models across quality, speed, fit, and context. It picks the best quantization for your memory and estimates tokens/...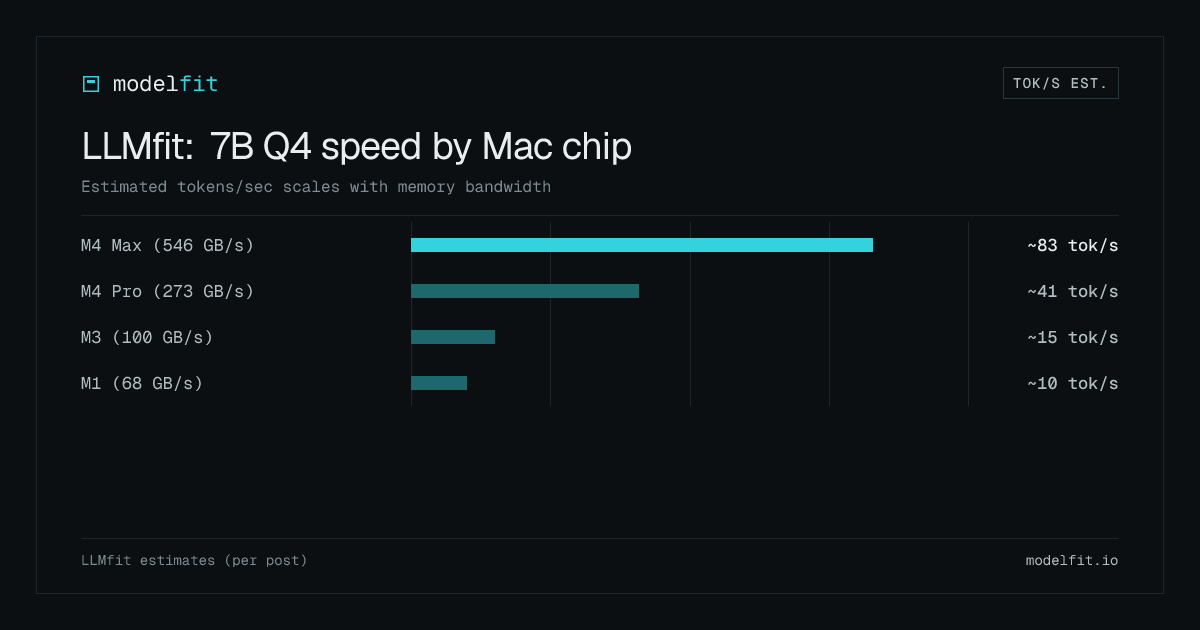
M5 Pro and M5 Max for Local LLMs (2026): What Runs, How Fast
> TL;DR: The M5 Pro and M5 Max bring Neural Accelerators to every GPU core, cutting prompt processing time 3.3-4x versus M4. A prompt that took 81 seconds now takes 18. The M5 Max's 128GB unified memo...
Qwen Team Exodus: 3 Key Leaders Leave Alibaba (2026)
> TL;DR: Qwen tech lead Lin Junyang, post-training head Yu Bowen, and staff researcher Binyuan Hui all left Alibaba in Q1 2026, during Qwen's most productive stretch ever: 9 models in 16 days, 1B+ dow...
Ollama 0.17: Up to 40% Faster on Apple Silicon
> TL;DR: Ollama 0.17 brings 10-15% faster prompt processing on Apple Silicon (up to 40% on NVIDIA), an 8-bit KV cache that halves context memory, and automatic context sizing based on your RAM. Update...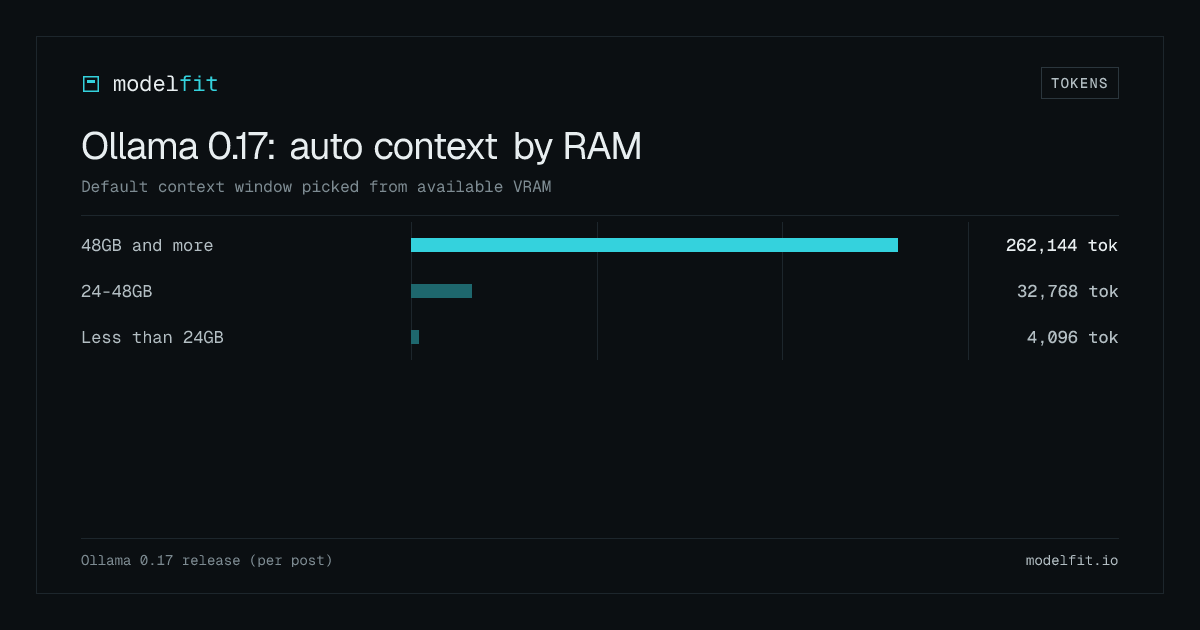
Claude Code on Local LLMs: Complete Setup Guide (2026)
> TL;DR: Claude Code can drive a local model through LiteLLM plus llama-server. Per @sudoingX, a 2x RTX 3090 rig (48GB VRAM) ran Qwen3-Coder-Next (80B MoE, 3B active) at 46 tokens per second, against ...
DeepSeek V3 vs Qwen 3.5 on Mac: Speed, RAM and Winner (2026)
> TL;DR: DeepSeek-V3 (671B total, 37B active) posts 88.5 on MMLU and 82.6 on HumanEval-Mul, but its size limits it to 96GB+ Mac Studios. Qwen3.5-35B-A3B scores 85.3 MMLU-Pro, fits a 24GB MacBook Pro, ...Local LLMs vs Cloud Flagships: SWE-Bench Results (2026)
Open-weight models now resolve 78.2% of SWE-Bench Verified tasks at the top of the local field, while the best cloud API reaches 97.0%. That gap of about 19 points is the honest headline for August 20...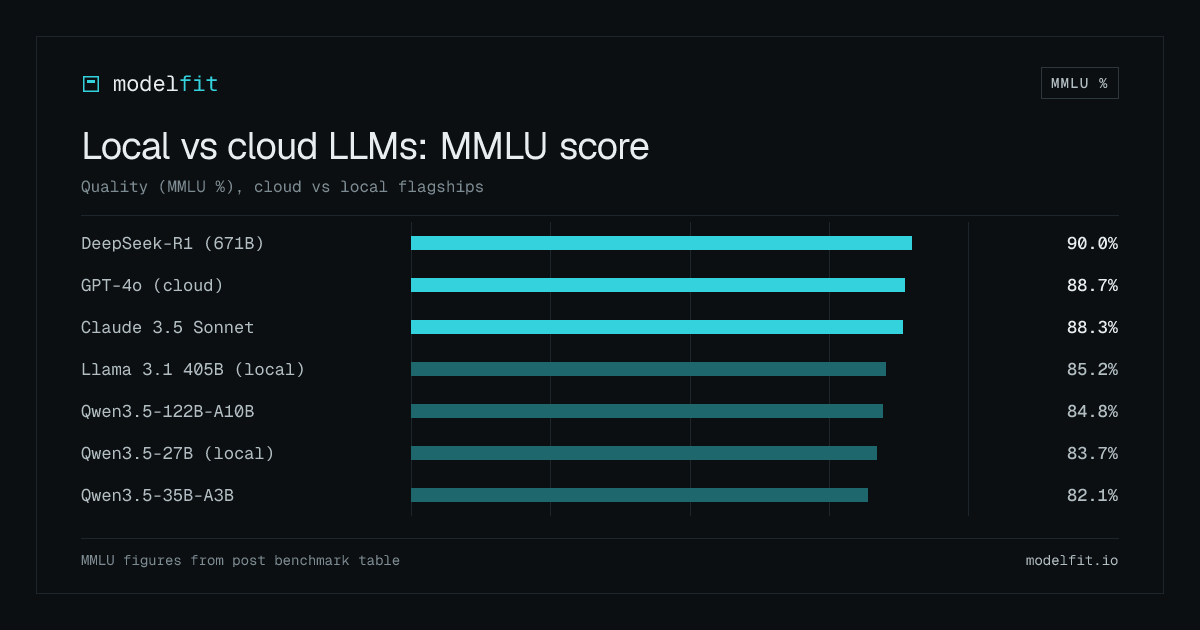
How to Install Ollama on Mac (Apple Silicon, 2026): M1-M5
> TL;DR: Run brew install ollama, then ollama run qwen3.5:4b. That's a capable local LLM on any Apple Silicon Mac with 8GB+ RAM in about 5 minutes. 16GB Macs should step up to Qwen3.5 9B; 24GB+ unlock...
MacBook Air vs Pro for Local LLMs (2026): Which Mac to Buy
> TL;DR: At the same chip and RAM, the ModelFit engine estimates the same speed on the MacBook Air M4 and the MacBook Pro M4, so the choice comes down to RAM options and cooling, not raw speed. For mo...