Best AI Models for MacBook Air M5 (2026)
AI model recommendations for MacBook Air M5 with up to 32GB RAM. The fastest fanless inference yet for Qwen3.5 and Gemma 4 class models. This configuration provides optimal performance for local AI models.
For a MacBook Air M5 with 24GB RAM, the best local LLM is Gemma 3 12B Instruct at ~17 tok/s. It loads in ~9.5GB of unified memory, and 65 of ModelFit's 106 local models fit this device comfortably (ModelFit, 2026).
Sizing rule: a local model needs about 0.6 GB of unified memory per billion parameters at Q4, and ModelFit budgets roughly 70% of the 24GB here so the OS, context, and KV-cache keep headroom (rising toward 85% on 128GB-and-up machines). Strong alternatives: Mistral Nemo 12B (~9.5GB) and GPT-OSS 20B (~13.8GB). Gemma 3 12B Instruct generates an estimated 17 tok/s here, fast enough for interactive chat. Longer contexts cost extra memory, so a model that fits at 8k context may not fit at 64k. What it will not run: Mistral Small 3.1 (Q8) (24B) needs about 23.3GB, more than this device's comfortable budget; models that large stay on a cloud API or a higher-memory machine.
Speeds are ModelFit estimates from chip bandwidth and model size, not measured benchmarks.
Cite this page: ModelFit, Best AI Models for MacBook Air M5 (2026), https://modelfit.io/macbook-air/m5/, updated September 2026, CC BY 4.0.
Last updated: September 15, 2026 · Editor: ModelFit Team
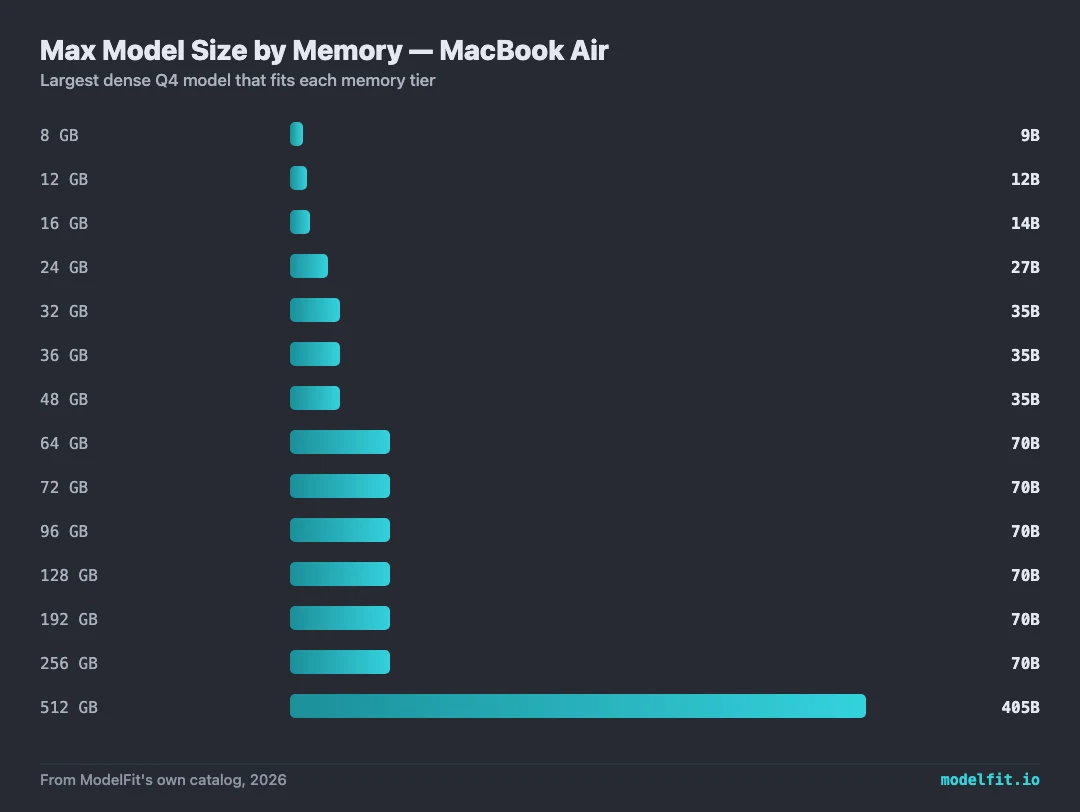
The M5 is the biggest Air leap yet for local AI: Apple gives every GPU core a Neural Accelerator, and unified memory bandwidth rises to 153 GB/s (+28% vs M4). With up to 32GB memory, the MacBook Air M5 runs 9B-14B models like Qwen3.5 9B faster than any previous Air. The fanless design still favors mid-size models over long sessions.
Based on our analysis, 8 out of 8 recommended models run excellently on this configuration. The sweet spot for MacBook Air with Apple M5 at 24GB is up to about 24B parameter models with Q4_K_M quantization, which provides the best trade-off between quality and inference speed. Higher-RAM configurations in the Apple M5 generation, including Pro and Max tiers where available, reach into the 7B-14B parameter range.
Optimized for Apple M5
Best for chat, quality. Strong fit for 24 GB RAM with balanced speed and quality.
Best for chat, translation. Strong fit for 24 GB RAM with balanced speed and quality.
This model may feel memory-heavy on 24 GB RAM, but it is still listed for balanced speed and quality.
Best for quality, coding, reasoning. Strong fit for 24 GB RAM with balanced speed and quality.
This model may feel memory-heavy on 24 GB RAM, but it is still listed for balanced speed and quality.
Best for quality, coding, reasoning. Strong fit for 24 GB RAM with balanced speed and quality.
This model may feel memory-heavy on 24 GB RAM, but it is still listed for balanced speed and quality.
Best for chat, coding. Strong fit for 24 GB RAM with balanced speed and quality.
Context costs memory too. Gemma 3 12B Instruct loads ~9.5 GB of weights; at 16k context the KV cache adds ~3.0 GB (still fits the ~17 GB usable RAM), and at 64k it adds ~12.0 GB (exceeds the budget, use a smaller quant or a q8_0 KV cache).
The model leaves about 4.3 GB of the usable unified memory budget free after weights and 16k context.
KV-cache figures assume an fp16 cache, the llama.cpp/Ollama default. Standard GQA models use a size-class estimate (8 KV heads x 128 head dim class); hybrid linear-attention models (Qwen3.5/3.6, Qwen3-Next) use the exact per-token cost from their published config, since only their sparse full-attention layers cache KV. A q8_0 KV cache roughly halves either figure. Estimates, not measurements.
Where to Buy for Local AI
best configsPrefer to buy direct? Buy from Apple (same price, no affiliate link).
Archive your model library off the internal drive. Quantized models run 5 to 40GB each, so 2TB holds dozens with room to spare.
Check price on Amazon40Gbps external storage fast enough to run models from. Pair it with an M.2 drive for a portable model vault.
Check price on AmazonThe fanless MacBook Air heat-soaks on long inference runs. An aluminum riser lifts the chassis so it sheds heat better off the desk.
Check price on AmazonMore ports for the external drives, displays and peripherals around a local-AI workstation.
Check price on AmazonModelFit may earn a commission on purchases through these links, at no extra cost to you.
What is the best AI model for MacBook Air with Apple M5?
With 24GB RAM and the Apple M5 chip, we recommend Gemma 3 12B Instruct for the best balance of speed and quality, handling models up to about 24B parameters at this RAM. Higher-RAM MacBook Air configurations in the Apple M5 generation, including Pro and Max tiers where available, reach into the 7B-14B parameter range.
How much RAM do I need for AI on MacBook Air Apple M5?
MacBook Air with Apple M5 supports 16, 24, 32GB configurations. For most AI workloads, 24GB provides good headroom. A 7B model typically needs 4-5GB of free RAM, while 14B models need 8-10GB.
How fast is Apple M5 for running local AI models?
Apple M5 on MacBook Air achieves an estimated 17 tokens per second with optimized models. The M5 is the biggest Air leap yet for local AI: Apple gives every GPU core a Neural Accelerator, and unified memory bandwidth rises to 153 GB/s (+28% vs M4). With up to 32GB memory, the MacBook Air M5 runs 9B-14B models like Qwen3.5 9B faster than any previous Air. The fanless design still favors mid-size models over long sessions. (Speeds are ModelFit estimates, not measured benchmarks.)
Can I run Ollama on MacBook Air Apple M5?
Yes, Ollama runs natively on Apple Silicon including Apple M5. You can install it in minutes and run models like Gemma 3 12B Instruct locally. Our wizard recommends the best models based on your exact Apple M5 configuration and available RAM.