01
Gemma 4 26B-A4B
Gemma / 26B / Q4_K_M / ~16 GB
Best for: Chat, Coding, Multimodal·Pop: 86/100
Perf: ~71 tok/s · first token ~0.4s
Local OKOKB · 26
Fits in 24 GB VRAM with room to spare. Best for chat, coding, multimodal on RTX 3090.
The RTX 3090 is the community favorite for local AI. With 24GB VRAM at $800-1000 on the used market, it runs 32B parameter models that most cards cannot touch. Expect ~87 tokens per second on 8B models and an estimated 27 tok/s on dense 32B, flagship-class capability at a fraction of current-gen prices.
The best local LLM for the RTX 3090 is Gemma 4 26B-A4B at ~71 tok/s on its 24GB VRAM. It uses ~16GB of VRAM; the RTX 3090 handles up to 32B parameter models at Q4. A 32B model at Q4 runs at ~27 tok/s. (ModelFit, 2026)
Sizing rule: a Q4 model needs about 0.6 GB of VRAM per billion parameters, and ModelFit budgets 90% of this card's 24GB for weights, context, and KV-cache. The per-size table below uses that same budget. Other strong fits: Qwen3.8 27B (27B, ~16.5GB) and Qwen3.5 27B Instruct (27B, ~16GB). Gemma 4 26B-A4B runs at an estimated 71 tok/s on this card. What it will not run: a 70B model does not fit in VRAM alone, so it spills to system RAM over PCIe and slows sharply.
Speeds are ModelFit estimates from memory bandwidth and model size, not measured benchmarks.
Cite this page: ModelFit, RTX 3090 24GB for Local LLMs: Runs 32B Q4, Used ~$900, https://modelfit.io/gpu/rtx-3090/, updated September 2026, CC BY 4.0.
Last updated: September 15, 2026 · Editor: ModelFit Team
*Used market price
| Model Size | Est. Speed | Fit on 24GB |
|---|---|---|
| 7B | ~97 tok/s | Fits in VRAM |
| 14B | ~54 tok/s | Fits in VRAM |
| 20B MoE (3.6B active) | ~83 tok/s | Fits in VRAM |
| 32B | ~27 tok/s | Fits in VRAM |
| 35B MoE (3B active) | ~70 tok/s | Fits in VRAM |
| 70B | ~1 tok/s | CPU offload (slow) |
| 120B MoE (5.1B active) | ~12 tok/s | CPU offload (slow) |
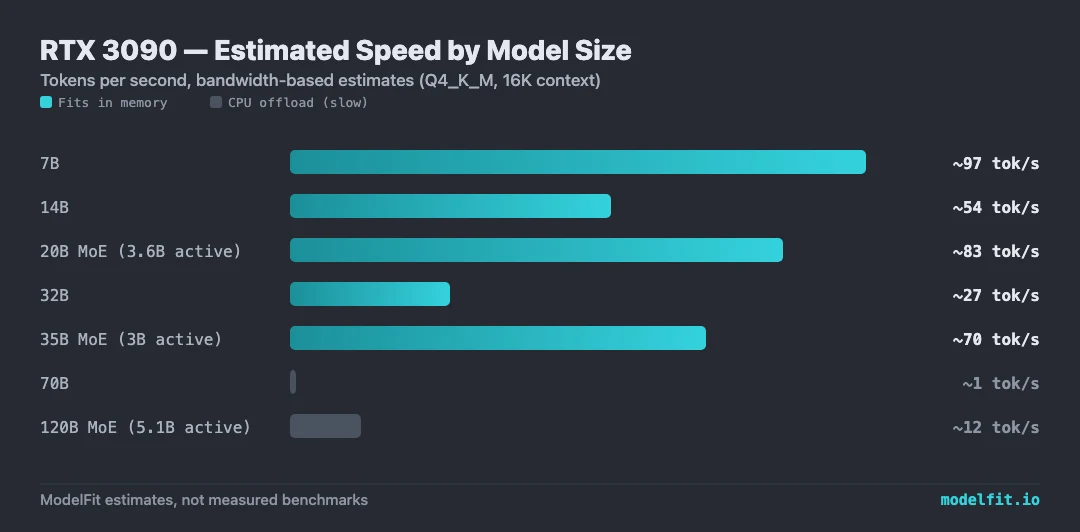
ModelFit estimates, not measured benchmarks: anchored to an 8B-class Q4_K_M model at 16K context on the RTX 3090's 936 GB/s bandwidth, then scaled by model size. MoE rows scale by active parameters (decode reads only the active experts), so a 35B MoE runs far faster than a dense 32B. "CPU offload" sizes exceed the 24GB VRAM; dense models slow to a crawl there, MoE models degrade less because hot experts stay GPU-resident.
Context costs VRAM too. Gemma 4 26B-A4B loads ~16 GB of weights; at 16k context the KV cache adds ~4.0 GB (still fits the ~22 GB usable VRAM), and at 64k it adds ~16.0 GB (exceeds the budget, use a smaller quant or a q8_0 KV cache).
The model leaves about 1.6 GB of the usable VRAM budget free after weights and 16k context.
KV-cache figures assume an fp16 cache, the llama.cpp/Ollama default. Standard GQA models use a size-class estimate (8 KV heads x 128 head dim class); hybrid linear-attention models (Qwen3.5/3.6, Qwen3-Next) use the exact per-token cost from their published config, since only their sparse full-attention layers cache KV. A q8_0 KV cache roughly halves either figure. Estimates, not measurements.
A Gen4 M.2 drive keeps your whole GGUF and quant collection on fast local storage, loading models straight off NVMe.
Check price on Amazon40Gbps external storage fast enough to run models from. Pair it with an M.2 drive for a portable model vault.
Check price on AmazonModelFit may earn a commission on purchases through these links, at no extra cost to you. Prices shown are approximate street references.
24GB GDDR6X at 936 GB/s unlocks a tier of models that 16GB cards cannot reach. DeepSeek-R1 32B, Qwen 2.5 32B, and Command-R 35B all fit comfortably at Q4 quantization. You get about 23GB usable, so 32B Q4 models (~20GB) load fully in VRAM with 3GB left for context. The 3090 is the cheapest way to run 32B models without CPU offloading, making it the darling of the r/LocalLLaMA community.
| Hardware | Memory | Speed | Bandwidth | Price |
|---|---|---|---|---|
| RTX 3090 | 24 GB | 87 tok/s | 936 GB/s | $900 |
| RTX 5080 | 16 GB | 94 tok/s | 960 GB/s | $1,570 |
| RTX 4080 SUPER | 16 GB | 79 tok/s | 736 GB/s | $1,600 |
| RTX 4090 | 24 GB | 104 tok/s | 1008 GB/s | $3,494 |
Gemma / 26B / Q4_K_M / ~16 GB
Best for: Chat, Coding, Multimodal·Pop: 86/100
Perf: ~71 tok/s · first token ~0.4s
Fits in 24 GB VRAM with room to spare. Best for chat, coding, multimodal on RTX 3090.
Qwen / 27B / Q4_K_M / ~16.5 GB
Best for: Coding, Agent, Vision, Long context·Pop: 95/100
Perf: ~31 tok/s · first token ~0.5s
Fits in 24 GB VRAM with room to spare. Best for coding, agent, vision, long context on RTX 3090.
Qwen / 27B / Q4_K_M / ~16 GB
Best for: Chat, Coding, Complex reasoning·Pop: 82/100
Perf: ~31 tok/s · first token ~0.5s
Fits in 24 GB VRAM with room to spare. Best for chat, coding, complex reasoning on RTX 3090.
GPT-OSS / 21B / MXFP4 / ~13.8 GB
Best for: Chat, Coding, Reasoning·Pop: 85/100
Perf: ~73 tok/s · first token ~0.4s
Fits in 24 GB VRAM with room to spare. Best for chat, coding, reasoning on RTX 3090.
Qwen / 27B / Q4_K_M / ~18 GB
Best for: Coding, Quality, Long context·Pop: 92/100
Perf: ~31 tok/s · first token ~0.5s
Fits in 24 GB VRAM with room to spare. Best for coding, quality, long context on RTX 3090.
LFM2 / 24B / Q4_K_M / ~14 GB
Best for: Local AI agents, privacy-first tool calling, MCP workflows·Pop: 80/100
Perf: ~98 tok/s · first token ~0.4s
Fits in 24 GB VRAM with room to spare. Best for local ai agents, privacy-first tool calling, mcp workflows on RTX 3090.
Gemma / 12B / Q8_0 / ~12.8 GB
Best for: Chat, Coding, Multimodal·Pop: 80/100
Perf: ~38 tok/s · first token ~0.4s
Fits in 24 GB VRAM with room to spare. Best for chat, coding, multimodal on RTX 3090.
Qwen / 35B / Q4_K_M / ~20 GB
Best for: Reasoning, Coding, Agent scenarios·Pop: 90/100
Perf: ~71 tok/s · first token ~1.0s
Fits in 24 GB VRAM with room to spare. Best for reasoning, coding, agent scenarios on RTX 3090.
Qwen / 14B / Q4_K_M / ~11 GB
Best for: Coding, Quality·Pop: 84/100
Perf: ~54 tok/s · first token ~0.4s
Fits in 24 GB VRAM with room to spare. Best for coding, quality on RTX 3090.
Qwen / 14B / Q8_0 / ~15.9 GB
Best for: Coding, Quality·Pop: 84/100
Perf: ~34 tok/s · first token ~0.4s
Fits in 24 GB VRAM with room to spare. Best for coding, quality on RTX 3090.
The RTX 3090 tops out around up to 32b parameter models. For anything bigger, an hourly rented GPU runs the same open weights with the same Ollama workflow, billed by the hour, no hardware purchase needed.
ModelFit may earn a commission on sign-ups made through these links, at no extra cost to you.
Alibaba Cloud: Widest size range (0.5B to 235B)
LlamaMeta: Most popular open-weight model family
DeepSeekDeepSeek AI: Best-in-class reasoning with R1 models
MistralMistral AI: Excellent performance-per-parameter ratio
GemmaGoogle DeepMind: Excellent quality at small sizes (1B-9B)
PhiMicrosoft: Best quality-per-gigabyte at small sizes
The RTX 3090 has 24GB GDDR6X VRAM with 936 GB/s bandwidth. About 23GB is usable for models. This is the cheapest GPU that can run 32B parameter models entirely in VRAM at Q4 quantization.
Up to 32B parameter models at Q4 quantization. Top picks: DeepSeek-R1 32B, Qwen 2.5 32B, and Command-R 35B. For 70B models, you would need Q2 quantization or dual GPUs.
Yes. The RTX 3090 is the best value GPU for large model inference in 2026. At $800-1000 on the used market, its 24GB VRAM handles 32B models that $999 16GB cards cannot. The r/LocalLLaMA community consistently ranks it as the top recommendation.
The RTX 4090 is 20% faster (an estimated 104 vs 87 tok/s on 8B) with the same 24GB VRAM. But it costs several times more once you compare a new 4090 against a used 3090. The 3090 offers much better value per dollar for AI workloads.
Check eBay, r/hardwareswap, and local marketplaces. Prices range from $800-1000. Look for cards that were not used for cryptocurrency mining. The Founders Edition and EVGA models have good cooling for sustained AI workloads.
ModelFit estimates a 32B model on the RTX 3090 runs at roughly 27 tok/s at Q4_K_M. The current 27B-class pick in the catalog is Qwen3.8 27B (ollama run qwen3.8:27b).
New open-weight models, real Apple Silicon benchmarks, and the one model worth running on your Mac this week. Free, one email a week, unsubscribe anytime.
By subscribing you agree to our Privacy Policy and to receive the weekly email. Unsubscribe anytime.
Use our interactive wizard to compare models across Apple Silicon and NVIDIA GPUs.