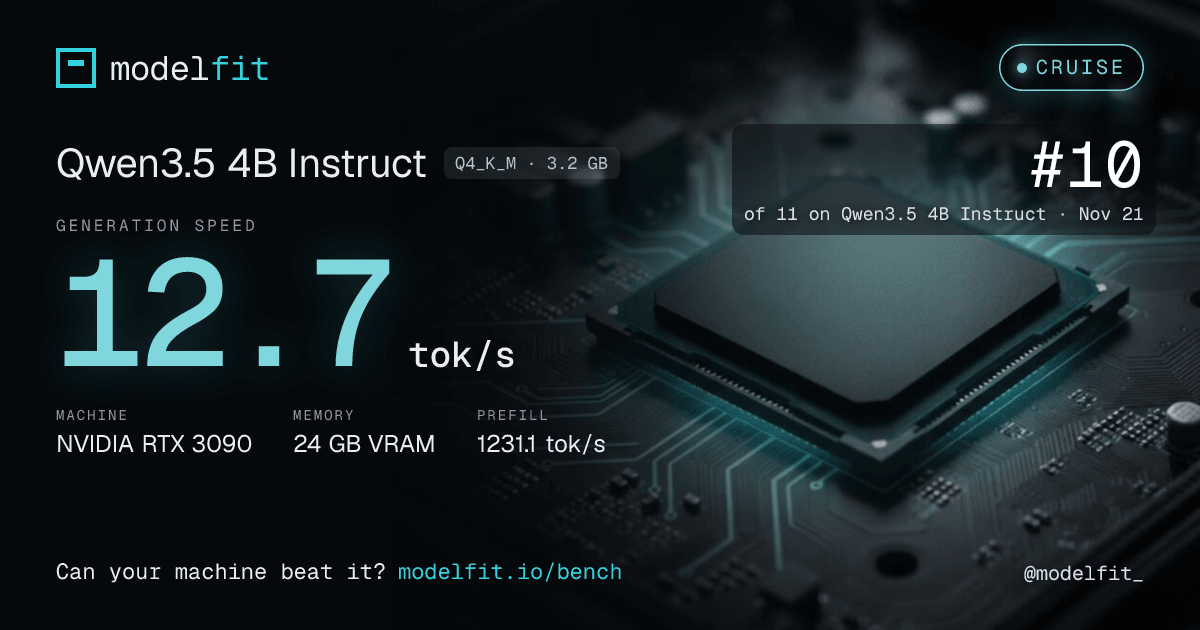
12.7 tok/s on Qwen3.5 4B Instruct
NVIDIA GeForce RTX 3090, measured with Ollama on 2026-11-21.
- Generation
- 12.7 tok/s
- Prompt reading
- 1231 tok/s
- Rank
- #10 of 11
- ModelFit estimate
- est. 195 tok/s
How this run was measured
- Machine
- NVIDIA GeForce RTX 3090
- Model
- Qwen3.5 4B Instruct · Q4_K_M · 3.2 GBqwen3.5:4b · classic decoding
- Method
- median of 3 runs · Ollama 0.32.15 · 4k context · 2026-11-21256 generated tokens per run, prompts of about 500 tokens
- Memory
- Part of the model ran off the GPUOllama could not fit it all in GPU memory
Measure your machine
$ npx @modelfit/cli@latest bench
Needs Node and Ollama. It picks a model that fits your machine and asks before it sends anything.
Get an email when a better model fits RTX 3090
Get one email when a new open-weight model is a better fit for this machine.
For: RTX 3090
You'll also get the weekly ModelFit email. By signing up you agree to our Privacy Policy. Unsubscribe from either email anytime, in one click.