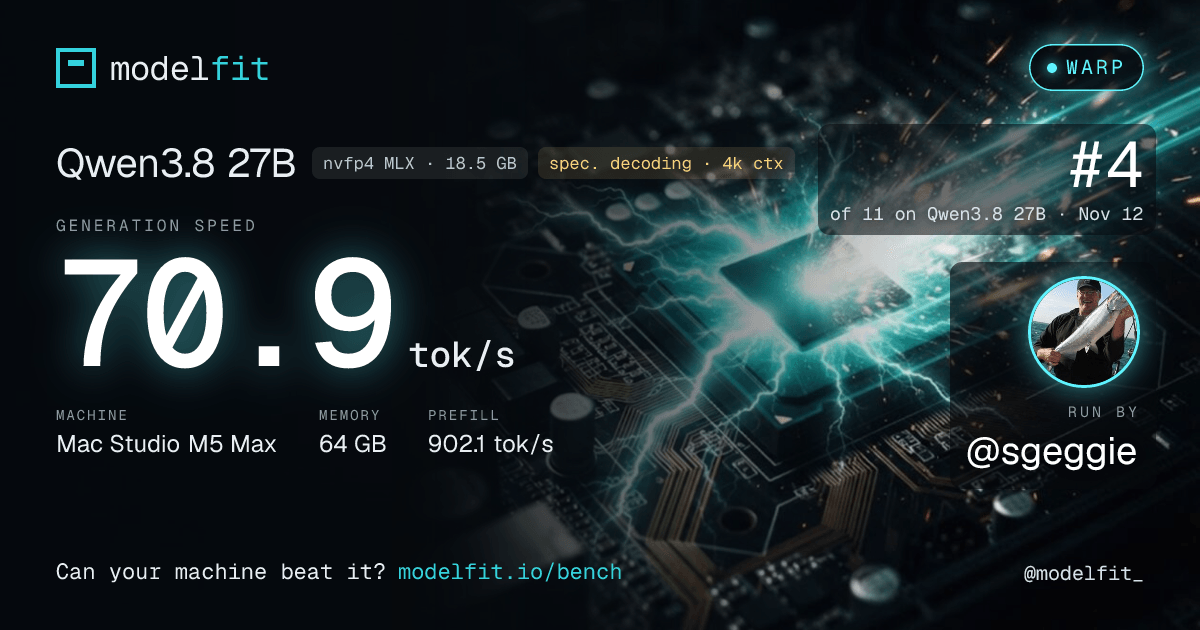
70.9 tok/s on Qwen3.8 27B
Apple M5 Max 40-core GPU · 64GB, measured with Ollama on 2026-11-12.
- Generation
- 70.9 tok/s
- Prompt reading
- 902 tok/s
- Rank
- #4 of 12
- ModelFit estimate
- est. 30 tok/s
How this run was measured
- Machine
- Apple M5 Max 40-core GPU · 64GB
- Model
- Qwen3.8 27B · nvfp4 MLX · 18.5 GB · spec. decoding · 4k ctxqwen3.8:27b · MLX runner · speculative decoding: several tokens per pass over the weights, ranked apart from classic runs
- Method
- median of 3 runs · Ollama 0.40.16 · 4k context · 2026-11-12256 generated tokens per run, prompts of about 500 tokens
- Posted by
- @sgeggie
Measure your machine
$ npx @modelfit/cli@latest bench
Needs Node and Ollama. It picks a model that fits your machine and asks before it sends anything.
Get an email when a better model fits Mac Studio M5 Max 64 GB
Get one email when a new open-weight model is a better fit for this machine.
For: Mac Studio M5 Max 64 GB
You'll also get the weekly ModelFit email. By signing up you agree to our Privacy Policy. Unsubscribe from either email anytime, in one click.