The Mac Studio M5 Ultra with 256GB unified memory, announced August 26, 2026, is the multi-model workstation. With 1.2 TB/s bandwidth - roughly 50% more than the M3 Ultra - and approximately 218GB usable for models after macOS overhead, this config moves past running one large model into running several at once. It loads 120B-class MoE models with comfortable margin, runs them at long context without compromise, and keeps a second model loaded alongside for agent routing or embedding search. This guide ranks the models that make the most of 256GB on the M5 Ultra, with speed estimates from the ModelFit engine.
TL;DR: The 256GB M5 Ultra is the multi-model / long-context box. Our top pick is Qwen3 235B-A22B at ~14 tok/s est. - a 235B MoE that becomes feasible for the first time here. For reliable daily reasoning, GPT-OSS 120B runs at ~43 tok/s est. with huge headroom, and Laguna S 2.1 delivers ~32 tok/s est. with strong agentic coding. See our Mac Studio M5 Ultra flagship article for full hardware context, the upgrade comparison for bandwidth differences, or the Mac Studio M5 Ultra model picker to rank every local LLM for your exact RAM tier.
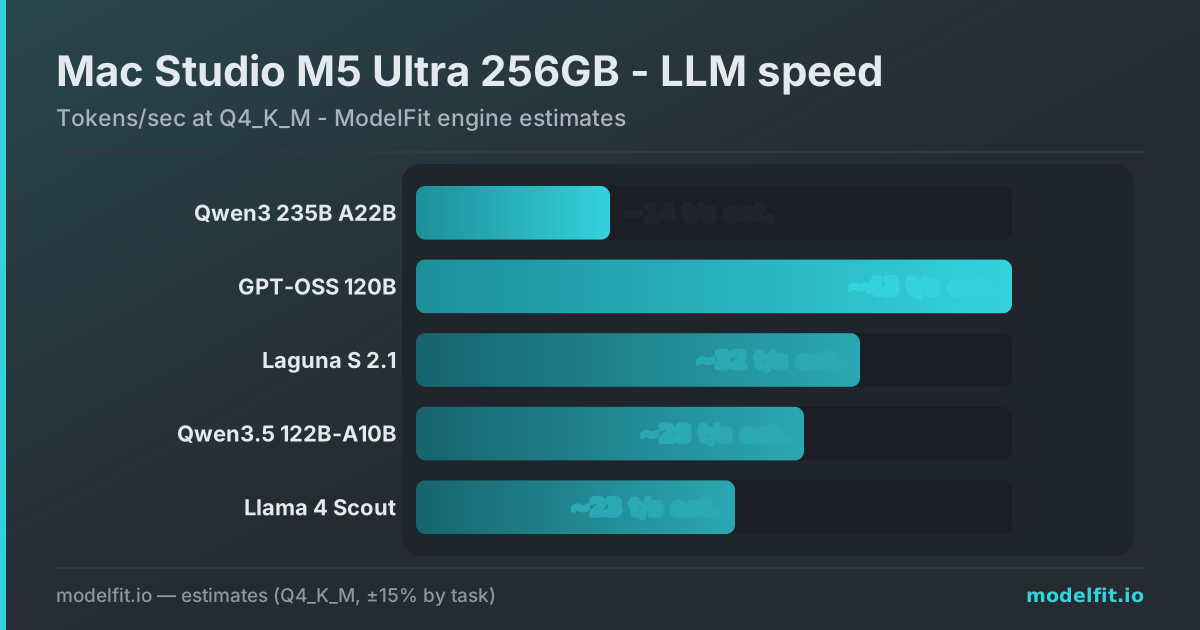 Estimated token generation on the Mac Studio M5 Ultra 256GB. ModelFit engine estimates.
How 256GB Shapes Your Model Choices
With ~218GB usable, the 256GB M5 Ultra has room for models that are too large for the 96GB tier and enough headroom to run them at long context without squeezing. The key difference from 96GB is not just capacity - it is the ability to run 120B-class MoE models at Q4 with ample KV-cache for 64K-128K context, and to keep a second model loaded for retrieval-augmented generation or embedding pipelines.
MoE models shine here. A Qwen3 235B-A22B loads at ~130GB, leaving ~88GB for KV-cache and system. At that context budget, you can run the model with 64K+ tokens of context while still having room for a small embedding model alongside it.
| Allocation | Size |
|---|---|
| macOS + system overhead | ~38 GB |
| Available for LLM | ~218 GB |
| Qwen3 235B-A22B (Q4) | ~130 GB |
| Two GPT-OSS 120B (MXFP4) | ~131 GB |
| GPT-OSS 120B + Qwen3-Next 80B (Q8) | ~150 GB |
Get told when a better model fits your Mac Studio M5 Max 64 GB
One email when a new open-weight model beats these picks on your machine, plus the Thursday weekly.
For: Mac Studio M5 Max 64 GB
Multi-model workflows are what set 256GB apart. You can load GPT-OSS 120B for reasoning work and Qwen3-Next 80B-A3B for high-speed chat without unloading either. Or run Laguna S 2.1 for agentic coding alongside a small embedding model for RAG. This is the config for people who write agents, not prompts.
Best Models Ranked
| Rank | Model | Type | Size | Est. tok/s | Best for |
|---|---|---|---|---|---|
| 1 | Qwen3 235B-A22B | MoE (22B active) | 235B | ~14 tok/s | Quality, reasoning |
| 2 | GPT-OSS 120B | MoE (5.1B active) | 117B | ~43 tok/s | Reasoning, coding, agents |
| 3 | Laguna S 2.1 | MoE (8B active) | 118B | ~32 tok/s | Agentic coding, long-horizon tasks |
| 4 | Qwen3.5 122B-A10B | MoE (10B active) | 122B | ~28 tok/s | Frontier-level reasoning |
| 5 | Llama 4 Scout | MoE (17B active) | 109B | ~23 tok/s | Long context, quality, multimodal |
| 6 | Qwen3-Next 80B-A3B (Q8) | MoE (3B active) | 80B | ~35 tok/s | Chat, coding at Q8 |
Release-day addition (August 26): Qwen3.8-Flash-Next, the open-weight Qwen4 architecture preview, now ranks second on this config in the engine at ~32 tok/s est. Its smallest GGUF build is ~123GB (1-bit, n-gram table included), so 256GB is the entry tier. See our launch coverage for the full hardware math.
Model Details
Qwen3 235B-A22B is the largest model that is practical on this config. Its 235B total parameters at Q4 load ~130GB, filling about 60% of usable memory. The 22B active parameters per token produce frontier-quality reasoning, at ~14 tok/s est. - slow for interactive chat but excellent for batch analysis, overnight agent runs, and complex coding tasks where quality matters more than speed.
ollama run qwen3:235b-a22b-q4_K_MGPT-OSS 120B is the most versatile model on this config. At ~65GB in MXFP4, it loads with roughly 150GB of headroom - enough for 128K+ context without any squeeze. Its 5.1B active parameters deliver ~43 tok/s est., making it a genuine daily driver for reasoning-heavy work. The huge headroom also means you can pair it with a second model without concern.
ollama run gpt-oss:120bLaguna S 2.1 (118B, MoE, 8B active) loads at ~96GB in Q4_K_M, leaving ~122GB free for a second model or large context. Its explicit focus on agentic coding and long-horizon tasks makes it a strong pair with GPT-OSS 120B for a multi-model agent pipeline. Expect ~32 tok/s est.
ollama run laguna-s-2.1:q4_K_MQwen3.5 122B-A10B fits at ~72GB in Q4_K_M with huge margin. Its 10B active parameters produce frontier-level reasoning at ~28 tok/s est., and the 146GB of leftover memory means you can load a high-speed chat model or an embedding model alongside it without compromise.
ollama run qwen3.5:122b-a10bLlama 4 Scout (109B, MoE, 17B active) loads at ~67GB in Q4_K_M, similarly light for this config. Its strength is long-context handling and multimodal input, making it the pick for document-heavy analysis workflows. At ~23 tok/s est., it is slower than GPT-OSS 120B (because its 17B active parameters outweigh GPT-OSS's 5.1B), but the capability tradeoff is worth it for image-including sessions.
ollama run llama4:scoutQwen3-Next 80B-A3B at Q8_0 is the precision play. At ~85GB in Q8, it leaves ~133GB free while giving near-lossless quality on its 3B active parameters. At ~35 tok/s est., it is the fastest Q8 model on this list and the best option for quality-sensitive chat and coding. Keep it loaded alongside a heavier reasoning model for best-of-both workflows.
ollama run qwen3-next:80b-a3b-instruct-q8_0What 256GB Can't Run
The 256GB M5 Ultra cannot run Llama 4 Maverick 400B or Llama 3.1 405B at Q4 (both need ~243GB). DeepSeek-R1 671B at Q4 (~380GB) is also out of reach. The 512GB tier is the minimum for those model classes.
That said, these are the only notable misses. Everything else from the 70B dense class through the 235B MoE class loads easily, often with room for a second model. If your work centers on multi-model agent workflows and long-context 120B-class MoE, 256GB is the right config. If you need 400B-class MoE models on your desk, step up to the 512GB M5 Ultra.
FAQ
Can the 256GB M5 Ultra run Llama 4 Maverick?
No. Llama 4 Maverick 400B needs about 245GB at Q4_K_M, which fills almost all of the 256GB and leaves no room for context. The 512GB config is the minimum for Maverick at usable speed (~12 tok/s est.).
What does 256GB unlock that 96GB does not?
The 256GB tier unlocks 235B-class MoE models like Qwen3 235B-A22B, multi-model serving (two 120B-class models simultaneously), and long-context sessions beyond 128K on 120B models. It also allows Q8 quantization for 80B-class models with full headroom.
Can I run two large models at once on 256GB?
Yes. GPT-OSS 120B (~65GB) plus Qwen3-Next 80B-A3B (~50GB) uses ~115GB combined, leaving over 100GB for system and context. You can also pair a large reasoning model with a small embedding model for RAG pipelines.
Is 256GB enough for production agent workloads?
For most agent workloads, yes. The capacity allows you to load a primary reasoning model, a fast chat model for routing, and an embedding model - all at once. The bandwidth keeps all of them responsive. If your agents handle multi-million-token context or use 400B-class models, move to the 512GB tier.
How does the 256GB M5 Ultra compare to the 256GB M3 Ultra?
The M5 Ultra offers roughly 50% more bandwidth (1.2 TB/s vs 819 GB/s), which translates to proportionally faster token generation. For 120B MoE models like gpt-oss-120b, the engine moves from ~29 tok/s est. to ~43 tok/s est. The 256GB config itself was unavailable on the M3 Ultra in 2026 due to DRAM shortages.
Don't miss the next one for your Mac Studio M5 Max 64 GB
This article covers one moment. Get one email when a newer open-weight model fits your machine better, plus the Thursday weekly with what changed.
For: Mac Studio M5 Max 64 GB
Where to Buy for Local AI
best configsArchive your model library off the internal drive. Quantized models run 5 to 40GB each, so 2TB holds dozens with room to spare.
Check price on Amazon40Gbps external storage fast enough to run models from. Pair it with an M.2 drive for a portable model vault.
Check price on AmazonMore ports for the external drives, displays and peripherals around a local-AI workstation.
Check price on AmazonComfortably runs 70B models at usable speed, the value pick for serious local AI.
Check price at AppleFrontierHeadroom for the largest open-weight models (Llama 4 Scout, big MoE) at home.
Check price at AppleModelFit may earn a commission on purchases through these links, at no extra cost to you.
Have questions? Reach out on X/Twitter